Compare commits
131 Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Deshraj Yadav |
fa34788df6 | ||
|
Deven Patel
|
0f4f220119 | ||
|
Deven Patel
|
512cfc9466 | ||
|
Deshraj Yadav
|
541b1cb7c7 | ||
|
Deven Patel
|
36af1a7615 | ||
|
Deshraj Yadav
|
b02e8feeda | ||
|
Deven Patel
|
406c46e7f4 | ||
|
Sidharth Mohanty
|
e35eaf1bfc | ||
|
Sidharth Mohanty
|
38426a7af1 | ||
|
Deshraj Yadav
|
141a23fb1e | ||
|
Sidharth Mohanty
|
bb28569abf | ||
|
Deshraj Yadav
|
1df46b2bb3 | ||
|
Deshraj Yadav
|
58f72e1ffe | ||
|
Deshraj Yadav
|
33409140b4 | ||
|
Deshraj Yadav
|
f6b80e01a1 | ||
|
Sidharth Mohanty
|
798d3fcc5a | ||
|
Sidharth Mohanty
|
85f3ac428b | ||
|
Deshraj Yadav
|
9fcf2130b5 | ||
|
Taranjeet Singh
|
51df00729e | ||
|
Deven Patel
|
023a61446f | ||
|
Deshraj Yadav
|
e0b73e6a5a | ||
|
Deven Patel
|
28460f725c | ||
|
Deshraj Yadav
|
c93e49d2b8 | ||
|
Deven Patel
|
07fb6bee54 | ||
|
Deshraj Yadav
|
3fa7db8420 | ||
|
Deven Patel
|
c14bd7b73b | ||
|
Sidharth Mohanty
|
5201beaab0 | ||
|
Sidharth Mohanty
|
122313d8a5 | ||
|
Deven Patel
|
82fd595306 | ||
|
Deven Patel
|
95c0d47236 | ||
|
Deven Patel
|
919cc74e94 | ||
|
Deshraj Yadav
|
d839991acb | ||
|
Deven Patel
|
539286aafd | ||
|
Sidharth Mohanty
|
23522b7b55 | ||
|
UnMonsieur
|
bf3fac56e4 | ||
|
Deshraj Yadav
|
a5bf8e9075 | ||
|
Deshraj Yadav
|
1d31b8f7e4 | ||
|
Deshraj Yadav
|
b144c7dccc | ||
|
Deshraj Yadav
|
1364975396 | ||
|
Deven Patel
|
deaa7f50f8 | ||
|
Sidharth Mohanty
|
744ab5156f | ||
|
Sidharth Mohanty
|
c45413969a | ||
|
Deshraj Yadav
|
b314e5e080 | ||
|
Deshraj Yadav
|
17129e2eaa | ||
|
Deven Patel
|
654fd8d74c | ||
|
Sidharth Mohanty
|
9d3568ef75 | ||
|
Sidharth Mohanty
|
14712cac88 | ||
|
Deshraj Yadav
|
0d568c758b | ||
|
Deshraj Yadav
|
7c6b88c7c5 | ||
|
Deshraj Yadav
|
32c93be46e | ||
|
Deven Patel
|
7de8d85199 | ||
|
Deshraj Yadav
|
f7dd65a3de | ||
|
Sidharth Mohanty
|
d8cdbe0041 | ||
|
Sidharth Mohanty
|
2b8b6d3ea9 | ||
|
Sidharth Mohanty
|
936c7e389f | ||
|
Sidharth Mohanty
|
6864b4207b | ||
|
Deshraj Yadav
|
98eb5b54be | ||
|
Deshraj Yadav
|
3332e6e236 | ||
|
Deven Patel
|
0533da72d7 | ||
|
Sidharth Mohanty
|
a1de238716 | ||
|
Deshraj Yadav
|
f0d112254b | ||
|
Sidharth Mohanty
|
830a7397ef | ||
|
Deven Patel
|
5428765329 | ||
|
Sidharth Mohanty
|
23c912f2b7 | ||
|
Sidharth Mohanty
|
9c4b023297 | ||
|
Deven Patel
|
53037b5ed8 | ||
|
Sidharth Mohanty
|
e2546a653d | ||
|
Deshraj Yadav
|
4b8cada873 | ||
|
Deshraj Yadav
|
fa3ca1d08a | ||
|
Sidharth Mohanty
|
8dd5cb9602 | ||
|
Deven Patel
|
a054f7be9c | ||
|
Deven Patel
|
df314dc6d1 | ||
|
Deven Patel
|
930280f4ce | ||
|
Deshraj Yadav
|
5022c1ae29 | ||
|
Deshraj Yadav
|
6ced756a6b | ||
|
Deshraj Yadav
|
b17268db50 | ||
|
Deshraj Yadav
|
476da37009 | ||
|
Deshraj Yadav
|
455f059c6f | ||
|
Deven Patel
|
5255a37c93 | ||
|
Deven Patel
|
68dc274f72 | ||
|
Deshraj Yadav
|
30228f7f8e | ||
|
Sidharth Mohanty
|
e15ef79ca9 | ||
|
Deshraj Yadav
|
bc012a7518 | ||
|
Sidharth Mohanty
|
3b4409cfad | ||
|
Deshraj Yadav
|
d3726134b2 | ||
|
anujshandillya
|
5acb7f1c55 | ||
|
Deshraj Yadav
|
81336668b3 | ||
|
Deshraj Yadav
|
35c2b83015 | ||
|
Deshraj Yadav
|
cc1ee1deaa | ||
|
Deshraj Yadav
|
29bd038579 | ||
|
Deshraj Yadav
|
f6c4f86986 | ||
|
Deven Patel
|
68183e9dce | ||
|
Deshraj Yadav
|
78ec91a3a9 | ||
|
Deven Patel
|
c95d458e52 | ||
|
Deshraj Yadav
|
191ae3ec1e | ||
|
Deshraj Yadav
|
ab9598d00a | ||
|
Deven Patel
|
0f8a2e624a | ||
|
Deven Patel
|
d77e8da3f3 | ||
|
Sidharth Mohanty
|
a27eeb3255 | ||
|
Deshraj Yadav
|
413ccb83e6 | ||
|
Deven Patel
|
797bb567c6 | ||
|
Deshraj Yadav
|
f2a5dc40ee | ||
|
Deshraj Yadav
|
3979480532 | ||
|
Abhinesh
|
76f1993e7a | ||
|
Deshraj Yadav
|
d783fa2b89 | ||
|
Sidharth Mohanty
|
bbce18caac | ||
|
Deshraj Yadav
|
3ce2d8a656 | ||
|
Deshraj Yadav
|
a5c86a2f5c | ||
|
Deshraj Yadav
|
d18e533adf | ||
|
Sidharth Mohanty
|
2b881aaad0 | ||
|
Sidharth Mohanty
|
39cc07608f | ||
|
Sidharth Mohanty
|
9894cfcced | ||
|
Sidharth Mohanty
|
b5d80be037 | ||
|
Sidharth Mohanty
|
b7870fbd9b | ||
|
Sidharth Mohanty
|
36e6d486fc | ||
|
Sidharth Mohanty
|
2d5dc84f1a | ||
|
Deshraj Yadav
|
b47405e1bd | ||
|
Muhammad Muzammil
|
8b64deab40 | ||
|
Rupesh Bansal
|
c8846e0e93 | ||
|
Deven Patel
|
7641cba01d | ||
|
Sidharth Mohanty
|
4dc1785ef1 | ||
|
Sidharth Mohanty
|
b2286f3e34 | ||
|
Sidharth Mohanty
|
65a20aa457 | ||
|
Rupesh Bansal
|
d8a7d71344 | ||
|
Deshraj Yadav
|
bb490df9a6 | ||
|
Rupesh Bansal
|
cdfd6519c8 | ||
|
Sidharth Mohanty
|
e8a2846449 | ||
|
Sidharth Mohanty
|
d065cbf934 | ||
|
Sidharth Mohanty
|
413b107b9a | ||
|
Deshraj Yadav
|
c336292346 | ||
|
Deshraj Yadav
|
adf50f1e81 |
@@ -3,7 +3,15 @@ name: ci
|
||||
on:
|
||||
push:
|
||||
branches: [main]
|
||||
paths:
|
||||
- 'embedchain/**'
|
||||
- 'tests/**'
|
||||
- 'examples/**'
|
||||
pull_request:
|
||||
paths:
|
||||
- 'embedchain/**'
|
||||
- 'tests/**'
|
||||
- 'examples/**'
|
||||
|
||||
jobs:
|
||||
build:
|
||||
@@ -19,14 +27,23 @@ jobs:
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
- name: Install poetry
|
||||
run: pip install poetry==1.4.2
|
||||
uses: snok/install-poetry@v1
|
||||
with:
|
||||
version: 1.4.2
|
||||
virtualenvs-create: true
|
||||
virtualenvs-in-project: true
|
||||
- name: Load cached venv
|
||||
id: cached-poetry-dependencies
|
||||
uses: actions/cache@v2
|
||||
with:
|
||||
path: .venv
|
||||
key: venv-${{ runner.os }}-${{ hashFiles('**/poetry.lock') }}
|
||||
- name: Install dependencies
|
||||
run: poetry install --all-extras
|
||||
if: steps.cached-poetry-dependencies.outputs.cache-hit != 'true'
|
||||
- name: Lint with ruff
|
||||
run: make lint
|
||||
- name: Test with pytest
|
||||
run: make test
|
||||
- name: Generate coverage report
|
||||
- name: Run tests and generate coverage report
|
||||
run: make coverage
|
||||
- name: Upload coverage reports to Codecov
|
||||
uses: codecov/codecov-action@v3
|
||||
@@ -34,4 +51,3 @@ jobs:
|
||||
file: coverage.xml
|
||||
env:
|
||||
CODECOV_TOKEN: ${{ secrets.CODECOV_TOKEN }}
|
||||
|
||||
|
||||
@@ -76,7 +76,6 @@ docs/_build/
|
||||
target/
|
||||
|
||||
# Jupyter Notebook
|
||||
.ipynb_checkpoints
|
||||
|
||||
# IPython
|
||||
profile_default/
|
||||
@@ -165,9 +164,14 @@ cython_debug/
|
||||
|
||||
# Database
|
||||
db
|
||||
test-db
|
||||
|
||||
.vscode
|
||||
/poetry.lock
|
||||
.idea/
|
||||
|
||||
.DS_Store
|
||||
|
||||
notebooks/*.yaml
|
||||
.ipynb_checkpoints/
|
||||
|
||||
!configs/*.yaml
|
||||
|
||||
@@ -1,10 +1,10 @@
|
||||
# Contributing to embedchain
|
||||
|
||||
Let us make contributing easy, collaborative and fun.
|
||||
Let us make contribution easy, collaborative and fun.
|
||||
|
||||
## Submit your Contribution through PR
|
||||
|
||||
To make a contribution, follow the following steps:
|
||||
To make a contribution, follow these steps:
|
||||
|
||||
1. Fork and clone this repository
|
||||
2. Do the changes on your fork with dedicated feature branch `feature/f1`
|
||||
@@ -35,7 +35,7 @@ poetry shell
|
||||
|
||||
### 📌 Pre-commit
|
||||
|
||||
To ensure our standards, make sure to install pre-commit before star to contribute.
|
||||
To ensure our standards, make sure to install pre-commit before starting to contribute.
|
||||
|
||||
```bash
|
||||
pre-commit install
|
||||
@@ -51,7 +51,7 @@ make lint
|
||||
|
||||
Make sure that the linter does not report any errors or warnings before submitting a pull request.
|
||||
|
||||
### Code Format with `black`
|
||||
### Code Formatting with `black`
|
||||
|
||||
We use `black` to reformat the code by running the following command:
|
||||
|
||||
|
||||
@@ -38,7 +38,7 @@ lint:
|
||||
poetry run ruff .
|
||||
|
||||
test:
|
||||
poetry run pytest
|
||||
poetry run pytest $(file)
|
||||
|
||||
coverage:
|
||||
poetry run pytest --cov=$(PROJECT_NAME) --cov-report=xml
|
||||
|
||||
@@ -1,62 +1,68 @@
|
||||
# embedchain
|
||||
<p align="center">
|
||||
<img src="docs/logo/dark.svg" width="400px" alt="Embedchain Logo">
|
||||
</p>
|
||||
|
||||
[](https://pypi.org/project/embedchain/)
|
||||
[](https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw)
|
||||
[](https://discord.gg/CUU9FPhRNt)
|
||||
[](https://twitter.com/embedchain)
|
||||
[](https://embedchain.substack.com/)
|
||||
[](https://colab.research.google.com/drive/138lMWhENGeEu7Q1-6lNbNTHGLZXBBz_B?usp=sharing)
|
||||
[](https://codecov.io/gh/embedchain/embedchain)
|
||||
<p align="center">
|
||||
<a href="https://runacap.com/ross-index/q3-2023/" target="_blank" rel="noopener"><img style="width: 260px; height: 56px" src="https://runacap.com/wp-content/uploads/2023/10/ROSS_badge_black_Q3_2023.svg" alt="ROSS Index - Fastest Growing Open-Source Startups in Q3 2023 | Runa Capital" width="260" height="56"/></a>
|
||||
</p>
|
||||
|
||||
Embedchain is a Data Platform for LLMs - load, index, retrieve, and sync any unstructured data. Using embedchain, you can easily create LLM powered apps over any data. If you want a javascript version, check out [embedchain-js](https://github.com/embedchain/embedchain/tree/main/embedchain-js)
|
||||
<p align="center">
|
||||
<a href="https://pypi.org/project/embedchain/">
|
||||
<img src="https://img.shields.io/pypi/v/embedchain" alt="PyPI">
|
||||
</a>
|
||||
<a href="https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw">
|
||||
<img src="https://img.shields.io/badge/slack-embedchain-brightgreen.svg?logo=slack" alt="Slack">
|
||||
</a>
|
||||
<a href="https://discord.gg/CUU9FPhRNt">
|
||||
<img src="https://dcbadge.vercel.app/api/server/6PzXDgEjG5?style=flat" alt="Discord">
|
||||
</a>
|
||||
<a href="https://twitter.com/embedchain">
|
||||
<img src="https://img.shields.io/twitter/follow/embedchain" alt="Twitter">
|
||||
</a>
|
||||
<a href="https://embedchain.substack.com/">
|
||||
<img src="https://img.shields.io/badge/Substack-%23006f5c.svg?logo=substack" alt="Substack">
|
||||
</a>
|
||||
<a href="https://colab.research.google.com/drive/138lMWhENGeEu7Q1-6lNbNTHGLZXBBz_B?usp=sharing">
|
||||
<img src="https://camo.githubusercontent.com/84f0493939e0c4de4e6dbe113251b4bfb5353e57134ffd9fcab6b8714514d4d1/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open in Colab">
|
||||
</a>
|
||||
<a href="https://codecov.io/gh/embedchain/embedchain">
|
||||
<img src="https://codecov.io/gh/embedchain/embedchain/graph/badge.svg?token=EMRRHZXW1Q" alt="codecov">
|
||||
</a>
|
||||
</p>
|
||||
|
||||
## Community
|
||||
<hr />
|
||||
|
||||
* Join embedchain community on slack by accepting [this invite](https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw)
|
||||
|
||||
## 🤝 Schedule a 1-on-1 Session
|
||||
|
||||
Book a [1-on-1 Session](https://cal.com/taranjeetio/ec) with Taranjeet, the founder, to discuss any issues, provide feedback, or explore how we can improve Embedchain for you.
|
||||
## What is Embedchain?
|
||||
Embedchain is a Data Platform for Large Language Models (LLMs). Seamlessly load, index, retrieve, and sync unstructured data to build dynamic, LLM-powered applications. Check out [embedchain-js](https://github.com/embedchain/embedchain/tree/main/embedchain-js) for a JavaScript implementation.
|
||||
|
||||
## 🔧 Quick install
|
||||
|
||||
### Python API
|
||||
```bash
|
||||
pip install --upgrade embedchain
|
||||
```
|
||||
|
||||
## 🔍 Demo
|
||||
### REST API
|
||||
You can also run Embedchain as a REST API server using the following command:
|
||||
|
||||
Try out embedchain in your browser:
|
||||
```bash
|
||||
docker run --name embedchain -p 8080:8080 embedchain/rest-api:latest
|
||||
```
|
||||
|
||||
[](https://colab.research.google.com/drive/17ON1LPonnXAtLaZEebnOktstB_1cJJmh?usp=sharing)
|
||||
Then, navigate to http://0.0.0.0:8080/docs to interact with the API.
|
||||
|
||||
## 📖 Documentation
|
||||
## 🔍 Usage and Demo
|
||||
|
||||
The documentation for embedchain can be found at [docs.embedchain.ai](https://docs.embedchain.ai).
|
||||
<!-- Demo GIF or Image -->
|
||||
<p align="center">
|
||||
<img src="docs/images/cover.gif" width="900px" alt="Embedchain Demo">
|
||||
</p>
|
||||
|
||||
## 💻 Usage
|
||||
|
||||
Embedchain empowers you to create ChatGPT like apps, on your own dynamic dataset.
|
||||
|
||||
### Data Types Supported
|
||||
|
||||
* Youtube video
|
||||
* PDF file
|
||||
* Web page
|
||||
* Sitemap
|
||||
* Doc file
|
||||
* Code documentation website loader
|
||||
* Notion and many more.
|
||||
|
||||
You can find the full list of data types on [our documentation](https://docs.embedchain.ai/data-sources/csv).
|
||||
|
||||
### Queries
|
||||
|
||||
For example, you can use Embedchain to create an Elon Musk bot using the following code:
|
||||
For example, you can create an Elon Musk bot using the following code:
|
||||
|
||||
```python
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# Create a bot instance
|
||||
os.environ["OPENAI_API_KEY"] = "YOUR API KEY"
|
||||
@@ -70,9 +76,40 @@ elon_bot.add("https://www.youtube.com/watch?v=RcYjXbSJBN8")
|
||||
# Query the bot
|
||||
elon_bot.query("How many companies does Elon Musk run and name those?")
|
||||
# Answer: Elon Musk currently runs several companies. As of my knowledge, he is the CEO and lead designer of SpaceX, the CEO and product architect of Tesla, Inc., the CEO and founder of Neuralink, and the CEO and founder of The Boring Company. However, please note that this information may change over time, so it's always good to verify the latest updates.
|
||||
|
||||
# (Optional): Deploy app to Embedchain Platform
|
||||
app.deploy()
|
||||
# 🔑 Enter your Embedchain API key. You can find the API key at https://app.embedchain.ai/settings/keys/
|
||||
# ec-xxxxxx
|
||||
|
||||
# 🛠️ Creating pipeline on the platform...
|
||||
# 🎉🎉🎉 Pipeline created successfully! View your pipeline: https://app.embedchain.ai/pipelines/xxxxx
|
||||
|
||||
# 🛠️ Adding data to your pipeline...
|
||||
# ✅ Data of type: web_page, value: https://www.forbes.com/profile/elon-musk added successfully.
|
||||
```
|
||||
|
||||
## 🤝 Contributing
|
||||
You can also try it in your browser with Google Colab:
|
||||
|
||||
[](https://colab.research.google.com/drive/17ON1LPonnXAtLaZEebnOktstB_1cJJmh?usp=sharing)
|
||||
|
||||
## 📖 Documentation
|
||||
Comprehensive guides and API documentation are available to help you get the most out of Embedchain:
|
||||
|
||||
- [Getting Started](https://docs.embedchain.ai/get-started/quickstart)
|
||||
- [Introduction](https://docs.embedchain.ai/get-started/introduction#what-is-embedchain)
|
||||
- [Examples](https://docs.embedchain.ai/get-started/examples)
|
||||
- [Supported data types](https://docs.embedchain.ai/data-sources/)
|
||||
|
||||
## 🔗 Join the Community
|
||||
|
||||
Connect with fellow developers and users by joining our [Slack Workspace](https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw). Dive into discussions, ask questions, and share your experiences.
|
||||
|
||||
## 🤝 Schedule a 1-on-1 Session
|
||||
|
||||
Book a [1-on-1 Session](https://cal.com/taranjeetio/ec) with Taranjeet, the founder, to discuss any issues, provide feedback, or explore how we can improve Embedchain for you.
|
||||
|
||||
## 🌐 Contributing
|
||||
|
||||
Contributions are welcome! Please check out the issues on the repository, and feel free to open a pull request.
|
||||
For more information, please see the [contributing guidelines](CONTRIBUTING.md).
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
llm:
|
||||
provider: anthropic
|
||||
model: 'claude-instant-1'
|
||||
config:
|
||||
model: 'claude-instant-1'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
|
||||
@@ -0,0 +1,19 @@
|
||||
app:
|
||||
config:
|
||||
id: azure-openai-app
|
||||
|
||||
llm:
|
||||
provider: azure_openai
|
||||
config:
|
||||
model: gpt-35-turbo
|
||||
deployment_name: your_llm_deployment_name
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
stream: false
|
||||
|
||||
embedder:
|
||||
provider: azure_openai
|
||||
config:
|
||||
model: text-embedding-ada-002
|
||||
deployment_name: you_embedding_model_deployment_name
|
||||
@@ -5,8 +5,8 @@ app:
|
||||
|
||||
llm:
|
||||
provider: openai
|
||||
model: 'gpt-3.5-turbo'
|
||||
config:
|
||||
model: 'gpt-3.5-turbo'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -23,4 +23,3 @@ embedder:
|
||||
provider: openai
|
||||
config:
|
||||
model: 'text-embedding-ada-002'
|
||||
deployment_name: null
|
||||
|
||||
@@ -0,0 +1,4 @@
|
||||
chunker:
|
||||
chunk_size: 100
|
||||
chunk_overlap: 20
|
||||
length_function: 'len'
|
||||
@@ -1,7 +1,7 @@
|
||||
llm:
|
||||
provider: cohere
|
||||
model: large
|
||||
config:
|
||||
model: large
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
|
||||
@@ -2,10 +2,15 @@ app:
|
||||
config:
|
||||
id: 'full-stack-app'
|
||||
|
||||
chunker:
|
||||
chunk_size: 100
|
||||
chunk_overlap: 20
|
||||
length_function: 'len'
|
||||
|
||||
llm:
|
||||
provider: openai
|
||||
model: 'gpt-3.5-turbo'
|
||||
config:
|
||||
model: 'gpt-3.5-turbo'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
|
||||
@@ -0,0 +1,8 @@
|
||||
llm:
|
||||
provider: openai
|
||||
config:
|
||||
model: 'gpt-4'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
stream: false
|
||||
@@ -1,7 +1,7 @@
|
||||
llm:
|
||||
provider: gpt4all
|
||||
model: 'orca-mini-3b.ggmlv3.q4_0.bin'
|
||||
config:
|
||||
model: 'orca-mini-3b-gguf2-q4_0.gguf'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -9,5 +9,3 @@ llm:
|
||||
|
||||
embedder:
|
||||
provider: gpt4all
|
||||
config:
|
||||
model: 'all-MiniLM-L6-v2'
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
llm:
|
||||
provider: huggingface
|
||||
model: 'google/flan-t5-xxl'
|
||||
config:
|
||||
model: 'google/flan-t5-xxl'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 0.5
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
llm:
|
||||
provider: llama2
|
||||
model: 'a16z-infra/llama13b-v2-chat:df7690f1994d94e96ad9d568eac121aecf50684a0b0963b25a41cc40061269e5'
|
||||
config:
|
||||
model: 'a16z-infra/llama13b-v2-chat:df7690f1994d94e96ad9d568eac121aecf50684a0b0963b25a41cc40061269e5'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 0.5
|
||||
|
||||
@@ -1,14 +1,14 @@
|
||||
app:
|
||||
config:
|
||||
id: 'my-app'
|
||||
log_level: 'WARN'
|
||||
log_level: 'WARNING'
|
||||
collect_metrics: true
|
||||
collection_name: 'my-app'
|
||||
|
||||
llm:
|
||||
provider: openai
|
||||
model: 'gpt-3.5-turbo'
|
||||
config:
|
||||
model: 'gpt-3.5-turbo'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -30,4 +30,4 @@ embedder:
|
||||
provider: openai
|
||||
config:
|
||||
model: 'text-embedding-ada-002'
|
||||
deployment_name: null
|
||||
deployment_name: 'my-app'
|
||||
|
||||
@@ -6,8 +6,8 @@ app:
|
||||
|
||||
llm:
|
||||
provider: gpt4all
|
||||
model: 'orca-mini-3b.ggmlv3.q4_0.bin'
|
||||
config:
|
||||
model: 'orca-mini-3b-gguf2-q4_0.gguf'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -23,5 +23,4 @@ vectordb:
|
||||
embedder:
|
||||
provider: gpt4all
|
||||
config:
|
||||
model: 'all-MiniLM-L6-v2'
|
||||
deployment_name: null
|
||||
deployment_name: 'test-deployment'
|
||||
|
||||
@@ -0,0 +1,26 @@
|
||||
pipeline:
|
||||
config:
|
||||
name: Example pipeline
|
||||
id: pipeline-1 # Make sure that id is different every time you create a new pipeline
|
||||
|
||||
vectordb:
|
||||
provider: chroma
|
||||
config:
|
||||
collection_name: pipeline-1
|
||||
dir: db
|
||||
allow_reset: true
|
||||
|
||||
llm:
|
||||
provider: gpt4all
|
||||
config:
|
||||
model: 'orca-mini-3b-gguf2-q4_0.gguf'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
stream: false
|
||||
|
||||
embedding_model:
|
||||
provider: gpt4all
|
||||
config:
|
||||
model: 'all-MiniLM-L6-v2'
|
||||
deployment_name: null
|
||||
@@ -1,6 +1,6 @@
|
||||
llm:
|
||||
provider: vertexai
|
||||
model: 'chat-bison'
|
||||
config:
|
||||
model: 'chat-bison'
|
||||
temperature: 0.5
|
||||
top_p: 0.5
|
||||
|
||||
@@ -0,0 +1,4 @@
|
||||
vectordb:
|
||||
provider: weaviate
|
||||
config:
|
||||
collection_name: my_weaviate_index
|
||||
@@ -1,5 +1,4 @@
|
||||
<Tip>
|
||||
If you can't find the specific data source, please feel free to request through one of the following channels and help us prioritize.
|
||||
<p>If you can't find the specific data source, please feel free to request through one of the following channels and help us prioritize.</p>
|
||||
|
||||
<CardGroup cols={2}>
|
||||
<Card title="Slack" icon="slack" href="https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw" color="#4A154B">
|
||||
@@ -15,4 +14,3 @@ If you can't find the specific data source, please feel free to request through
|
||||
Schedule a call with Embedchain founder
|
||||
</Card>
|
||||
</CardGroup>
|
||||
</Tip>
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
<Tip>
|
||||
If you can't find the specific LLM you need, no need to fret. We're continuously expanding our support for additional LLMs, and you can help us prioritize by opening an issue on our GitHub or simply reaching out to us on our Slack or Discord community.
|
||||
<p>If you can't find the specific LLM you need, no need to fret. We're continuously expanding our support for additional LLMs, and you can help us prioritize by opening an issue on our GitHub or simply reaching out to us on our Slack or Discord community.</p>
|
||||
|
||||
<CardGroup cols={2}>
|
||||
<Card title="Slack" icon="slack" href="https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw" color="#4A154B">
|
||||
@@ -15,4 +14,3 @@ If you can't find the specific LLM you need, no need to fret. We're continuously
|
||||
Schedule a call with Embedchain founder
|
||||
</Card>
|
||||
</CardGroup>
|
||||
</Tip>
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
<Tip>
|
||||
If you can't find the specific vector database, please feel free to request through one of the following channels and help us prioritize.
|
||||
|
||||
|
||||
<p>If you can't find the specific vector database, please feel free to request through one of the following channels and help us prioritize.</p>
|
||||
|
||||
<CardGroup cols={2}>
|
||||
<Card title="Slack" icon="slack" href="https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw" color="#4A154B">
|
||||
@@ -15,4 +16,3 @@ If you can't find the specific vector database, please feel free to request thro
|
||||
Schedule a call with Embedchain founder
|
||||
</Card>
|
||||
</CardGroup>
|
||||
</Tip>
|
||||
|
||||
@@ -6,15 +6,21 @@ Embedchain is made to work out of the box. However, for advanced users we're als
|
||||
|
||||
You can configure different components of your app (`llm`, `embedding model`, or `vector database`) through a simple yaml configuration that Embedchain offers. Here is a generic full-stack example of the yaml config:
|
||||
|
||||
```yaml
|
||||
|
||||
<Tip>
|
||||
Embedchain applications are configurable using YAML file, JSON file or by directly passing the config dictionary.
|
||||
</Tip>
|
||||
|
||||
<CodeGroup>
|
||||
```yaml config.yaml
|
||||
app:
|
||||
config:
|
||||
id: 'full-stack-app'
|
||||
name: 'full-stack-app'
|
||||
|
||||
llm:
|
||||
provider: openai
|
||||
model: 'gpt-3.5-turbo'
|
||||
config:
|
||||
model: 'gpt-3.5-turbo'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -42,34 +48,138 @@ embedder:
|
||||
provider: openai
|
||||
config:
|
||||
model: 'text-embedding-ada-002'
|
||||
|
||||
chunker:
|
||||
chunk_size: 2000
|
||||
chunk_overlap: 100
|
||||
length_function: 'len'
|
||||
```
|
||||
|
||||
```json config.json
|
||||
{
|
||||
"app": {
|
||||
"config": {
|
||||
"name": "full-stack-app"
|
||||
}
|
||||
},
|
||||
"llm": {
|
||||
"provider": "openai",
|
||||
"config": {
|
||||
"model": "gpt-3.5-turbo",
|
||||
"temperature": 0.5,
|
||||
"max_tokens": 1000,
|
||||
"top_p": 1,
|
||||
"stream": false,
|
||||
"template": "Use the following pieces of context to answer the query at the end.\nIf you don't know the answer, just say that you don't know, don't try to make up an answer.\n$context\n\nQuery: $query\n\nHelpful Answer:",
|
||||
"system_prompt": "Act as William Shakespeare. Answer the following questions in the style of William Shakespeare."
|
||||
}
|
||||
},
|
||||
"vectordb": {
|
||||
"provider": "chroma",
|
||||
"config": {
|
||||
"collection_name": "full-stack-app",
|
||||
"dir": "db",
|
||||
"allow_reset": true
|
||||
}
|
||||
},
|
||||
"embedder": {
|
||||
"provider": "openai",
|
||||
"config": {
|
||||
"model": "text-embedding-ada-002"
|
||||
}
|
||||
},
|
||||
"chunker": {
|
||||
"chunk_size": 2000,
|
||||
"chunk_overlap": 100,
|
||||
"length_function": "len"
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
```python config.py
|
||||
config = {
|
||||
'app': {
|
||||
'config': {
|
||||
'name': 'full-stack-app'
|
||||
}
|
||||
},
|
||||
'llm': {
|
||||
'provider': 'openai',
|
||||
'config': {
|
||||
'model': 'gpt-3.5-turbo',
|
||||
'temperature': 0.5,
|
||||
'max_tokens': 1000,
|
||||
'top_p': 1,
|
||||
'stream': False,
|
||||
'template': (
|
||||
"Use the following pieces of context to answer the query at the end.\n"
|
||||
"If you don't know the answer, just say that you don't know, don't try to make up an answer.\n"
|
||||
"$context\n\nQuery: $query\n\nHelpful Answer:"
|
||||
),
|
||||
'system_prompt': (
|
||||
"Act as William Shakespeare. Answer the following questions in the style of William Shakespeare."
|
||||
)
|
||||
}
|
||||
},
|
||||
'vectordb': {
|
||||
'provider': 'chroma',
|
||||
'config': {
|
||||
'collection_name': 'full-stack-app',
|
||||
'dir': 'db',
|
||||
'allow_reset': True
|
||||
}
|
||||
},
|
||||
'embedder': {
|
||||
'provider': 'openai',
|
||||
'config': {
|
||||
'model': 'text-embedding-ada-002'
|
||||
}
|
||||
},
|
||||
'chunker': {
|
||||
'chunk_size': 2000,
|
||||
'chunk_overlap': 100,
|
||||
'length_function': 'len'
|
||||
}
|
||||
}
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
Alright, let's dive into what each key means in the yaml config above:
|
||||
|
||||
1. `app` Section:
|
||||
- `config`:
|
||||
- `id` (String): The ID or name of your full-stack application.
|
||||
- `name` (String): The name of your full-stack application.
|
||||
- `id` (String): The id of your full-stack application.
|
||||
<Note>Only use this to reload already created apps. We recommend users to not create their own ids.</Note>
|
||||
- `collect_metrics` (Boolean): Indicates whether metrics should be collected for the app, defaults to `True`
|
||||
- `log_level` (String): The log level for the app, defaults to `WARNING`
|
||||
2. `llm` Section:
|
||||
- `provider` (String): The provider for the language model, which is set to 'openai'. You can find the full list of llm providers in [our docs](/components/llms).
|
||||
- `model` (String): The specific model being used, 'gpt-3.5-turbo'.
|
||||
- `config`:
|
||||
- `model` (String): The specific model being used, 'gpt-3.5-turbo'.
|
||||
- `temperature` (Float): Controls the randomness of the model's output. A higher value (closer to 1) makes the output more random.
|
||||
- `max_tokens` (Integer): Controls how many tokens are used in the response.
|
||||
- `top_p` (Float): Controls the diversity of word selection. A higher value (closer to 1) makes word selection more diverse.
|
||||
- `stream` (Boolean): Controls if the response is streamed back to the user (set to false).
|
||||
- `template` (String): A custom template for the prompt that the model uses to generate responses.
|
||||
- `system_prompt` (String): A system prompt for the model to follow when generating responses, in this case, it's set to the style of William Shakespeare.
|
||||
- `stream` (Boolean): Controls if the response is streamed back to the user (set to false).
|
||||
- `number_documents` (Integer): Number of documents to pull from the vectordb as context, defaults to 1
|
||||
3. `vectordb` Section:
|
||||
- `provider` (String): The provider for the vector database, set to 'chroma'. You can find the full list of vector database providers in [our docs](/components/vector-databases).
|
||||
- `config`:
|
||||
- `collection_name` (String): The initial collection name for the database, set to 'full-stack-app'.
|
||||
- `dir` (String): The directory for the database, set to 'db'.
|
||||
- `allow_reset` (Boolean): Indicates whether resetting the database is allowed, set to true.
|
||||
- `collection_name` (String): The initial collection name for the vectordb, set to 'full-stack-app'.
|
||||
- `dir` (String): The directory for the local database, set to 'db'.
|
||||
- `allow_reset` (Boolean): Indicates whether resetting the vectordb is allowed, set to true.
|
||||
<Note>We recommend you to checkout vectordb specific config [here](https://docs.embedchain.ai/components/vector-databases)</Note>
|
||||
4. `embedder` Section:
|
||||
- `provider` (String): The provider for the embedder, set to 'openai'. You can find the full list of embedding model providers in [our docs](/components/embedding-models).
|
||||
- `config`:
|
||||
- `model` (String): The specific model used for text embedding, 'text-embedding-ada-002'.
|
||||
|
||||
5. `chunker` Section:
|
||||
- `chunk_size` (Integer): The size of each chunk of text that is sent to the language model.
|
||||
- `chunk_overlap` (Integer): The amount of overlap between each chunk of text.
|
||||
- `length_function` (String): The function used to calculate the length of each chunk of text. In this case, it's set to 'len'. You can also use any function import directly as a string here.
|
||||
If you have questions about the configuration above, please feel free to reach out to us using one of the following methods:
|
||||
|
||||
<Snippet file="get-help.mdx" />
|
||||
@@ -8,6 +8,7 @@ Embedchain supports several embedding models from the following providers:
|
||||
|
||||
<CardGroup cols={4}>
|
||||
<Card title="OpenAI" href="#openai"></Card>
|
||||
<Card title="Azure OpenAI" href="#azure-openai"></Card>
|
||||
<Card title="GPT4All" href="#gpt4all"></Card>
|
||||
<Card title="Hugging Face" href="#hugging-face"></Card>
|
||||
<Card title="Vertex AI" href="#vertex-ai"></Card>
|
||||
@@ -23,12 +24,12 @@ Once you have obtained the key, you can use it like this:
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ['OPENAI_API_KEY'] = 'xxx'
|
||||
|
||||
# load embedding model configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
|
||||
app.add("https://en.wikipedia.org/wiki/OpenAI")
|
||||
app.query("What is OpenAI?")
|
||||
@@ -43,6 +44,45 @@ embedder:
|
||||
|
||||
</CodeGroup>
|
||||
|
||||
## Azure OpenAI
|
||||
|
||||
To use Azure OpenAI embedding model, you have to set some of the azure openai related environment variables as given in the code block below:
|
||||
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ["OPENAI_API_TYPE"] = "azure"
|
||||
os.environ["AZURE_OPENAI_ENDPOINT"] = "https://xxx.openai.azure.com/"
|
||||
os.environ["AZURE_OPENAI_API_KEY"] = "xxx"
|
||||
os.environ["OPENAI_API_VERSION"] = "xxx"
|
||||
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: azure_openai
|
||||
config:
|
||||
model: gpt-35-turbo
|
||||
deployment_name: your_llm_deployment_name
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
stream: false
|
||||
|
||||
embedder:
|
||||
provider: azure_openai
|
||||
config:
|
||||
model: text-embedding-ada-002
|
||||
deployment_name: you_embedding_model_deployment_name
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
You can find the list of models and deployment name on the [Azure OpenAI Platform](https://oai.azure.com/portal).
|
||||
|
||||
## GPT4ALL
|
||||
|
||||
GPT4All supports generating high quality embeddings of arbitrary length documents of text using a CPU optimized contrastively trained Sentence Transformer.
|
||||
@@ -50,17 +90,17 @@ GPT4All supports generating high quality embeddings of arbitrary length document
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load embedding model configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: gpt4all
|
||||
model: 'orca-mini-3b.ggmlv3.q4_0.bin'
|
||||
config:
|
||||
model: 'orca-mini-3b-gguf2-q4_0.gguf'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -68,8 +108,6 @@ llm:
|
||||
|
||||
embedder:
|
||||
provider: gpt4all
|
||||
config:
|
||||
model: 'all-MiniLM-L6-v2'
|
||||
```
|
||||
|
||||
</CodeGroup>
|
||||
@@ -81,17 +119,17 @@ Hugging Face supports generating embeddings of arbitrary length documents of tex
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load embedding model configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: huggingface
|
||||
model: 'google/flan-t5-xxl'
|
||||
config:
|
||||
model: 'google/flan-t5-xxl'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 0.5
|
||||
@@ -112,17 +150,17 @@ Embedchain supports Google's VertexAI embeddings model through a simple interfac
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load embedding model configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: vertexai
|
||||
model: 'chat-bison'
|
||||
config:
|
||||
model: 'chat-bison'
|
||||
temperature: 0.5
|
||||
top_p: 0.5
|
||||
|
||||
|
||||
@@ -26,7 +26,7 @@ Once you have obtained the key, you can use it like this:
|
||||
|
||||
```python
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ['OPENAI_API_KEY'] = 'xxx'
|
||||
|
||||
@@ -41,19 +41,19 @@ If you are looking to configure the different parameters of the LLM, you can do
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ['OPENAI_API_KEY'] = 'xxx'
|
||||
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: openai
|
||||
model: 'gpt-3.5-turbo'
|
||||
config:
|
||||
model: 'gpt-3.5-turbo'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -65,7 +65,42 @@ llm:
|
||||
|
||||
## Azure OpenAI
|
||||
|
||||
_Coming soon_
|
||||
To use Azure OpenAI model, you have to set some of the azure openai related environment variables as given in the code block below:
|
||||
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ["OPENAI_API_TYPE"] = "azure"
|
||||
os.environ["OPENAI_API_BASE"] = "https://xxx.openai.azure.com/"
|
||||
os.environ["OPENAI_API_KEY"] = "xxx"
|
||||
os.environ["OPENAI_API_VERSION"] = "xxx"
|
||||
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: azure_openai
|
||||
config:
|
||||
model: gpt-35-turbo
|
||||
deployment_name: your_llm_deployment_name
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
stream: false
|
||||
|
||||
embedder:
|
||||
provider: azure_openai
|
||||
config:
|
||||
model: text-embedding-ada-002
|
||||
deployment_name: you_embedding_model_deployment_name
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
You can find the list of models and deployment name on the [Azure OpenAI Platform](https://oai.azure.com/portal).
|
||||
|
||||
## Anthropic
|
||||
|
||||
@@ -75,19 +110,19 @@ To use anthropic's model, please set the `ANTHROPIC_API_KEY` which you find on t
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ["ANTHROPIC_API_KEY"] = "xxx"
|
||||
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: anthropic
|
||||
model: 'claude-instant-1'
|
||||
config:
|
||||
model: 'claude-instant-1'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -112,19 +147,19 @@ Once you have the API key, you are all set to use it with Embedchain.
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ["COHERE_API_KEY"] = "xxx"
|
||||
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: cohere
|
||||
model: large
|
||||
config:
|
||||
model: large
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -145,17 +180,17 @@ GPT4all is a free-to-use, locally running, privacy-aware chatbot. No GPU or inte
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: gpt4all
|
||||
model: 'orca-mini-3b.ggmlv3.q4_0.bin'
|
||||
config:
|
||||
model: 'orca-mini-3b-gguf2-q4_0.gguf'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -163,8 +198,6 @@ llm:
|
||||
|
||||
embedder:
|
||||
provider: gpt4all
|
||||
config:
|
||||
model: 'all-MiniLM-L6-v2'
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
@@ -179,11 +212,11 @@ Once you have the key, load the app using the config yaml file:
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ["JINACHAT_API_KEY"] = "xxx"
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
@@ -204,7 +237,7 @@ llm:
|
||||
Install related dependencies using the following command:
|
||||
|
||||
```bash
|
||||
pip install --upgrade 'embedchain[huggingface_hub]'
|
||||
pip install --upgrade 'embedchain[huggingface-hub]'
|
||||
```
|
||||
|
||||
First, set `HUGGINGFACE_ACCESS_TOKEN` in environment variable which you can obtain from [their platform](https://huggingface.co/settings/tokens).
|
||||
@@ -215,19 +248,19 @@ Once you have the token, load the app using the config yaml file:
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ["HUGGINGFACE_ACCESS_TOKEN"] = "xxx"
|
||||
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: huggingface
|
||||
model: 'google/flan-t5-xxl'
|
||||
config:
|
||||
model: 'google/flan-t5-xxl'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 0.5
|
||||
@@ -245,19 +278,19 @@ Once you have the token, load the app using the config yaml file:
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ["REPLICATE_API_TOKEN"] = "xxx"
|
||||
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: llama2
|
||||
model: 'a16z-infra/llama13b-v2-chat:df7690f1994d94e96ad9d568eac121aecf50684a0b0963b25a41cc40061269e5'
|
||||
config:
|
||||
model: 'a16z-infra/llama13b-v2-chat:df7690f1994d94e96ad9d568eac121aecf50684a0b0963b25a41cc40061269e5'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 0.5
|
||||
@@ -272,17 +305,17 @@ Setup Google Cloud Platform application credentials by following the instruction
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load llm configuration from config.yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
llm:
|
||||
provider: vertexai
|
||||
model: 'chat-bison'
|
||||
config:
|
||||
model: 'chat-bison'
|
||||
temperature: 0.5
|
||||
top_p: 0.5
|
||||
```
|
||||
|
||||
@@ -22,10 +22,10 @@ Utilizing a vector database alongside Embedchain is a seamless process. All you
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load chroma configuration from yaml file
|
||||
app = App.from_config(yaml_path="config1.yaml")
|
||||
app = App.from_config(config_path="config1.yaml")
|
||||
```
|
||||
|
||||
```yaml config1.yaml
|
||||
@@ -61,10 +61,10 @@ pip install --upgrade 'embedchain[elasticsearch]'
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load elasticsearch configuration from yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
@@ -73,8 +73,11 @@ vectordb:
|
||||
config:
|
||||
collection_name: 'es-index'
|
||||
es_url: http://localhost:9200
|
||||
allow_reset: true
|
||||
http_auth:
|
||||
- admin
|
||||
- admin
|
||||
api_key: xxx
|
||||
verify_certs: false
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
@@ -89,22 +92,22 @@ pip install --upgrade 'embedchain[opensearch]'
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load opensearch configuration from yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
vectordb:
|
||||
provider: opensearch
|
||||
config:
|
||||
collection_name: 'my-app'
|
||||
opensearch_url: 'https://localhost:9200'
|
||||
http_auth:
|
||||
- admin
|
||||
- admin
|
||||
vector_dimension: 1536
|
||||
collection_name: 'my-app'
|
||||
use_ssl: false
|
||||
verify_certs: false
|
||||
```
|
||||
@@ -119,20 +122,26 @@ Install related dependencies using the following command:
|
||||
pip install --upgrade 'embedchain[milvus]'
|
||||
```
|
||||
|
||||
Set the Zilliz environment variables `ZILLIZ_CLOUD_URI` and `ZILLIZ_CLOUD_TOKEN` which you can find it on their [cloud platform](https://cloud.zilliz.com/).
|
||||
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
import os
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ['ZILLIZ_CLOUD_URI'] = 'https://xxx.zillizcloud.com'
|
||||
os.environ['ZILLIZ_CLOUD_TOKEN'] = 'xxx'
|
||||
|
||||
# load zilliz configuration from yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
vectordb:
|
||||
provider: zilliz
|
||||
config:
|
||||
collection_name: 'zilliz-app'
|
||||
collection_name: 'zilliz_app'
|
||||
uri: https://xxxx.api.gcp-region.zillizcloud.com
|
||||
token: xxx
|
||||
vector_dim: 1536
|
||||
@@ -147,13 +156,21 @@ _Coming soon_
|
||||
|
||||
## Pinecone
|
||||
|
||||
Install pinecone related dependencies using the following command:
|
||||
|
||||
```bash
|
||||
pip install --upgrade 'embedchain[pinecone]'
|
||||
```
|
||||
|
||||
In order to use Pinecone as vector database, set the environment variables `PINECONE_API_KEY` and `PINECONE_ENV` which you can find on [Pinecone dashboard](https://app.pinecone.io/).
|
||||
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load pinecone configuration from yaml file
|
||||
app = App.from_config(yaml_path="config.yaml")
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
@@ -165,12 +182,46 @@ vectordb:
|
||||
collection_name: my-pinecone-index
|
||||
```
|
||||
|
||||
</CodeGroup>
|
||||
|
||||
## Qdrant
|
||||
|
||||
_Coming soon_
|
||||
In order to use Qdrant as a vector database, set the environment variables `QDRANT_URL` and `QDRANT_API_KEY` which you can find on [Qdrant Dashboard](https://cloud.qdrant.io/).
|
||||
|
||||
<CodeGroup>
|
||||
```python main.py
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load qdrant configuration from yaml file
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
vectordb:
|
||||
provider: qdrant
|
||||
config:
|
||||
collection_name: my_qdrant_index
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
## Weaviate
|
||||
|
||||
_Coming soon_
|
||||
In order to use Weaviate as a vector database, set the environment variables `WEAVIATE_ENDPOINT` and `WEAVIATE_API_KEY` which you can find on [Weaviate dashboard](https://console.weaviate.cloud/dashboard).
|
||||
|
||||
<CodeGroup>
|
||||
```python main.py
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# load weaviate configuration from yaml file
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
|
||||
```yaml config.yaml
|
||||
vectordb:
|
||||
provider: weaviate
|
||||
config:
|
||||
collection_name: my_weaviate_index
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
<Snippet file="missing-vector-db-tip.mdx" />
|
||||
|
||||
@@ -5,7 +5,7 @@ title: '📊 CSV'
|
||||
To add any csv file, use the data_type as `csv`. `csv` allows remote urls and conventional file paths. Headers are included for each line, so if you have an `age` column, `18` will be added as `age: 18`. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
app.add('https://people.sc.fsu.edu/~jburkardt/data/csv/airtravel.csv', data_type="csv")
|
||||
|
||||
@@ -0,0 +1,41 @@
|
||||
---
|
||||
title: '⚙️ Custom'
|
||||
---
|
||||
|
||||
When we say "custom", we mean that you can customize the loader and chunker to your needs. This is done by passing a custom loader and chunker to the `add` method.
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
import your_loader
|
||||
import your_chunker
|
||||
|
||||
app = App()
|
||||
loader = your_loader()
|
||||
chunker = your_chunker()
|
||||
|
||||
app.add("source", data_type="custom", loader=loader, chunker=chunker)
|
||||
```
|
||||
|
||||
<Note>
|
||||
The custom loader and chunker must be a class that inherits from the [`BaseLoader`](https://github.com/embedchain/embedchain/blob/main/embedchain/loaders/base_loader.py) and [`BaseChunker`](https://github.com/embedchain/embedchain/blob/main/embedchain/chunkers/base_chunker.py) classes respectively.
|
||||
</Note>
|
||||
|
||||
<Note>
|
||||
If the `data_type` is not a valid data type, the `add` method will fallback to the `custom` data type and expect a custom loader and chunker to be passed by the user.
|
||||
</Note>
|
||||
|
||||
Example:
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
from embedchain.loaders.github import GithubLoader
|
||||
|
||||
app = App()
|
||||
|
||||
loader = GithubLoader(config={"token": "ghp_xxx"})
|
||||
|
||||
app.add("repo:embedchain/embedchain type:repo", data_type="github", loader=loader)
|
||||
|
||||
app.query("What is Embedchain?")
|
||||
# Answer: Embedchain is a Data Platform for Large Language Models (LLMs). It allows users to seamlessly load, index, retrieve, and sync unstructured data in order to build dynamic, LLM-powered applications. There is also a JavaScript implementation called embedchain-js available on GitHub.
|
||||
```
|
||||
@@ -35,7 +35,7 @@ Default behavior is to create a persistent vector db in the directory **./db**.
|
||||
Create a local index:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
naval_chat_bot = App()
|
||||
naval_chat_bot.add("https://www.youtube.com/watch?v=3qHkcs3kG44")
|
||||
@@ -45,8 +45,20 @@ naval_chat_bot.add("https://navalmanack.s3.amazonaws.com/Eric-Jorgenson_The-Alma
|
||||
You can reuse the local index with the same code, but without adding new documents:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
naval_chat_bot = App()
|
||||
print(naval_chat_bot.query("What unique capacity does Naval argue humans possess when it comes to understanding explanations or concepts?"))
|
||||
```
|
||||
|
||||
## Resetting an app and vector database
|
||||
|
||||
You can reset the app by simply calling the `reset` method. This will delete the vector database and all other app related files.
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
app.add("https://www.youtube.com/watch?v=3qHkcs3kG44")
|
||||
app.reset()
|
||||
```
|
||||
|
||||
@@ -0,0 +1,28 @@
|
||||
---
|
||||
title: "💬 Discord"
|
||||
---
|
||||
|
||||
To add any Discord channel messages to your app, just add the `channel_id` as the source and set the `data_type` to `discord`.
|
||||
|
||||
<Note>
|
||||
This loader requires a Discord bot token with read messages access.
|
||||
To obtain the token, follow the instructions provided in this tutorial:
|
||||
<a href="https://www.writebots.com/discord-bot-token/">How to Get a Discord Bot Token?</a>.
|
||||
</Note>
|
||||
|
||||
```python
|
||||
import os
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# add your discord "BOT" token
|
||||
os.environ["DISCORD_TOKEN"] = "xxx"
|
||||
|
||||
app = App()
|
||||
|
||||
app.add("1177296711023075338", data_type="discord")
|
||||
|
||||
response = app.query("What is Joe saying about Elon Musk?")
|
||||
|
||||
print(response)
|
||||
# Answer: Joe is saying "Elon Musk is a genius".
|
||||
```
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
title: '🗨️ Discourse'
|
||||
---
|
||||
|
||||
You can now easily load data from your community built with [Discourse](https://discourse.org/).
|
||||
|
||||
## Example
|
||||
|
||||
1. Setup the Discourse Loader with your community url.
|
||||
```Python
|
||||
from embedchain.loaders.discourse import DiscourseLoader
|
||||
|
||||
dicourse_loader = DiscourseLoader(config={"domain": "https://community.openai.com"})
|
||||
```
|
||||
|
||||
2. Once you setup the loader, you can create an app and load data using the above discourse loader
|
||||
```Python
|
||||
import os
|
||||
from embedchain.pipeline import Pipeline as App
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-xxx"
|
||||
|
||||
app = App()
|
||||
|
||||
app.add("openai after:2023-10-1", data_type="discourse", loader=dicourse_loader)
|
||||
|
||||
question = "Where can I find the OpenAI API status page?"
|
||||
app.query(question)
|
||||
# Answer: You can find the OpenAI API status page at https:/status.openai.com/.
|
||||
```
|
||||
|
||||
NOTE: The `add` function of the app will accept any executable search query to load data. Refer [Discourse API Docs](https://docs.discourse.org/#tag/Search) to learn more about search queries.
|
||||
|
||||
3. We automatically create a chunker to chunk your discourse data, however if you wish to provide your own chunker class. Here is how you can do that:
|
||||
```Python
|
||||
|
||||
from embedchain.chunkers.discourse import DiscourseChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
|
||||
discourse_chunker_config = ChunkerConfig(chunk_size=1000, chunk_overlap=0, length_function=len)
|
||||
discourse_chunker = DiscourseChunker(config=discourse_chunker_config)
|
||||
|
||||
app.add("openai", data_type='discourse', loader=dicourse_loader, chunker=discourse_chunker)
|
||||
```
|
||||
@@ -1,11 +1,11 @@
|
||||
---
|
||||
title: '📚🌐 Code documentation'
|
||||
title: '📚 Code documentation'
|
||||
---
|
||||
|
||||
To add any code documentation website as a loader, use the data_type as `docs_site`. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
app.add("https://docs.embedchain.ai/", data_type="docs_site")
|
||||
|
||||
@@ -7,7 +7,7 @@ title: '📄 Docx file'
|
||||
To add any doc/docx file, use the data_type as `docx`. `docx` allows remote urls and conventional file paths. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
app.add('https://example.com/content/intro.docx', data_type="docx")
|
||||
|
||||
@@ -0,0 +1,50 @@
|
||||
---
|
||||
title: 📝 Github
|
||||
---
|
||||
|
||||
1. Setup the Github loader by configuring the Github account with username and personal access token (PAT). Check out [this](https://docs.github.com/en/enterprise-server@3.6/authentication/keeping-your-account-and-data-secure/managing-your-personal-access-tokens#creating-a-personal-access-token) link to learn how to create a PAT.
|
||||
```Python
|
||||
from embedchain.loaders.github import GithubLoader
|
||||
|
||||
loader = GithubLoader(
|
||||
config={
|
||||
"token":"ghp_xxxx"
|
||||
}
|
||||
)
|
||||
```
|
||||
|
||||
2. Once you setup the loader, you can create an app and load data using the above Github loader
|
||||
```Python
|
||||
import os
|
||||
from embedchain.pipeline import Pipeline as App
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-xxxx"
|
||||
|
||||
app = App()
|
||||
|
||||
app.add("repo:embedchain/embedchain type:repo", data_type="github", loader=loader)
|
||||
|
||||
response = app.query("What is Embedchain?")
|
||||
# Answer: Embedchain is a Data Platform for Large Language Models (LLMs). It allows users to seamlessly load, index, retrieve, and sync unstructured data in order to build dynamic, LLM-powered applications. There is also a JavaScript implementation called embedchain-js available on GitHub.
|
||||
```
|
||||
The `add` function of the app will accept any valid github query with qualifiers. It only supports loading github code, repository, issues and pull-requests.
|
||||
<Note>
|
||||
You must provide qualifiers `type:` and `repo:` in the query. The `type:` qualifier can be a combination of `code`, `repo`, `pr`, `issue`. The `repo:` qualifier must be a valid github repository name.
|
||||
</Note>
|
||||
|
||||
<Card title="Valid queries" icon="lightbulb" iconType="duotone" color="#ca8b04">
|
||||
- `repo:embedchain/embedchain type:repo` - to load the repository
|
||||
- `repo:embedchain/embedchain type:issue,pr` - to load the issues and pull-requests of the repository
|
||||
- `repo:embedchain/embedchain type:issue state:closed` - to load the closed issues of the repository
|
||||
</Card>
|
||||
|
||||
3. We automatically create a chunker to chunk your GitHub data, however if you wish to provide your own chunker class. Here is how you can do that:
|
||||
```Python
|
||||
from embedchain.chunkers.common_chunker import CommonChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
|
||||
github_chunker_config = ChunkerConfig(chunk_size=2000, chunk_overlap=0, length_function=len)
|
||||
github_chunker = CommonChunker(config=github_chunker_config)
|
||||
|
||||
app.add(load_query, data_type="github", loader=loader, chunker=github_chunker)
|
||||
```
|
||||
@@ -0,0 +1,34 @@
|
||||
---
|
||||
title: '📬 Gmail'
|
||||
---
|
||||
|
||||
To use GmailLoader you must install the extra dependencies with `pip install --upgrade embedchain[gmail]`.
|
||||
|
||||
The `source` must be a valid Gmail search query, you can refer `https://support.google.com/mail/answer/7190?hl=en` to build a query.
|
||||
|
||||
To load Gmail messages, you MUST use the data_type as `gmail`. Otherwise the source will be detected as simple `text`.
|
||||
|
||||
To use this you need to save `credentials.json` in the directory from where you will run the loader. Follow these steps to get the credentials
|
||||
|
||||
1. Go to the [Google Cloud Console](https://console.cloud.google.com/apis/credentials).
|
||||
2. Create a project if you don't have one already.
|
||||
3. Create an `OAuth Consent Screen` in the project. You may need to select the `external` option.
|
||||
4. Make sure the consent screen is published.
|
||||
5. Enable the [Gmail API](https://console.cloud.google.com/apis/api/gmail.googleapis.com)
|
||||
6. Create credentials from the `Credentials` tab.
|
||||
7. Select the type `OAuth Client ID`.
|
||||
8. Choose the application type `Web application`. As a name you can choose `embedchain` or any other name as per your use case.
|
||||
9. Add an authorized redirect URI for `http://localhost:8080/`.
|
||||
10. You can leave everything else at default, finish the creation.
|
||||
11. When you are done, a modal opens where you can download the details in `json` format.
|
||||
12. Put the `.json` file in your current directory and rename it to `credentials.json`
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
gmail_filter = "to: me label:inbox"
|
||||
app.add(gmail_filter, data_type="gmail")
|
||||
app.query("Summarize my email conversations")
|
||||
```
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
title: '📃 JSON'
|
||||
---
|
||||
|
||||
To add any json file, use the data_type as `json`. Headers are included for each line, so for example if you have a json like `{"age": 18}`, then it will be added as `age: 18`.
|
||||
|
||||
Here are the supported sources for loading `json`:
|
||||
|
||||
```
|
||||
1. URL - valid url to json file that ends with ".json" extension.
|
||||
2. Local file - valid url to local json file that ends with ".json" extension.
|
||||
3. String - valid json string (e.g. - app.add('{"foo": "bar"}'))
|
||||
```
|
||||
|
||||
<Tip>
|
||||
If you would like to add other data structures (e.g. list, dict etc.), convert it to a valid json first using `json.dumps()` function.
|
||||
</Tip>
|
||||
|
||||
## Example
|
||||
|
||||
<CodeGroup>
|
||||
|
||||
```python python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
# Add json file
|
||||
app.add("temp.json")
|
||||
|
||||
app.query("What is the net worth of Elon Musk as of October 2023?")
|
||||
# As of October 2023, Elon Musk's net worth is $255.2 billion.
|
||||
```
|
||||
|
||||
|
||||
```json temp.json
|
||||
{
|
||||
"question": "What is your net worth, Elon Musk?",
|
||||
"answer": "As of October 2023, Elon Musk's net worth is $255.2 billion, making him one of the wealthiest individuals in the world."
|
||||
}
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
|
||||
@@ -5,7 +5,7 @@ title: '📝 Mdx file'
|
||||
To add any `.mdx` file to your app, use the data_type (first argument to `.add()` method) as `mdx`. Note that this supports support mdx file present on machine, so this should be a file path. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
app.add('path/to/file.mdx', data_type='mdx')
|
||||
|
||||
@@ -0,0 +1,47 @@
|
||||
---
|
||||
title: '🐬 MySQL'
|
||||
---
|
||||
|
||||
1. Setup the MySQL loader by configuring the SQL db.
|
||||
```Python
|
||||
from embedchain.loaders.mysql import MySQLLoader
|
||||
|
||||
config = {
|
||||
"host": "host",
|
||||
"port": "port",
|
||||
"database": "database",
|
||||
"user": "username",
|
||||
"password": "password",
|
||||
}
|
||||
|
||||
mysql_loader = MySQLLoader(config=config)
|
||||
```
|
||||
|
||||
For more details on how to setup with valid config, check MySQL [documentation](https://dev.mysql.com/doc/connector-python/en/connector-python-connectargs.html).
|
||||
|
||||
2. Once you setup the loader, you can create an app and load data using the above MySQL loader
|
||||
```Python
|
||||
from embedchain.pipeline import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
app.add("SELECT * FROM table_name;", data_type='mysql', loader=mysql_loader)
|
||||
# Adds `(1, 'What is your net worth, Elon Musk?', "As of October 2023, Elon Musk's net worth is $255.2 billion.")`
|
||||
|
||||
response = app.query(question)
|
||||
# Answer: As of October 2023, Elon Musk's net worth is $255.2 billion.
|
||||
```
|
||||
|
||||
NOTE: The `add` function of the app will accept any executable query to load data. DO NOT pass the `CREATE`, `INSERT` queries in `add` function.
|
||||
|
||||
3. We automatically create a chunker to chunk your SQL data, however if you wish to provide your own chunker class. Here is how you can do that:
|
||||
``Python
|
||||
|
||||
from embedchain.chunkers.mysql import MySQLChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
|
||||
mysql_chunker_config = ChunkerConfig(chunk_size=1000, chunk_overlap=0, length_function=len)
|
||||
mysql_chunker = MySQLChunker(config=mysql_chunker_config)
|
||||
|
||||
app.add("SELECT * FROM table_name;", data_type='mysql', loader=mysql_loader, chunker=mysql_chunker)
|
||||
```
|
||||
@@ -2,13 +2,13 @@
|
||||
title: '📓 Notion'
|
||||
---
|
||||
|
||||
To use notion you must install the extra dependencies with `pip install --upgrade embedchain[notion]`.
|
||||
To use notion you must install the extra dependencies with `pip install --upgrade embedchain[community]`.
|
||||
|
||||
To load a notion page, use the data_type as `notion`. Since it is hard to automatically detect, it is advised to specify the `data_type` when adding a notion document.
|
||||
The next argument must **end** with the `notion page id`. The id is a 32-character string. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
|
||||
@@ -0,0 +1,22 @@
|
||||
---
|
||||
title: 🙌 OpenAPI
|
||||
---
|
||||
|
||||
To add any OpenAPI spec yaml file (currently the json file will be detected as JSON data type), use the data_type as 'openapi'. 'openapi' allows remote urls and conventional file paths.
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
app.add("https://github.com/openai/openai-openapi/blob/master/openapi.yaml", data_type="openapi")
|
||||
# Or add using the local file path
|
||||
# app.add("configs/openai_openapi.yaml", data_type="openapi")
|
||||
|
||||
app.query("What can OpenAI API endpoint do? Can you list the things it can learn from?")
|
||||
# Answer: The OpenAI API endpoint allows users to interact with OpenAI's models and perform various tasks such as generating text, answering questions, summarizing documents, translating languages, and more. The specific capabilities and tasks that the API can learn from may vary depending on the models and features provided by OpenAI. For more detailed information, it is recommended to refer to the OpenAI API documentation at https://platform.openai.com/docs/api-reference.
|
||||
```
|
||||
|
||||
<Note>
|
||||
The yaml file added to the App must have the required OpenAPI fields otherwise the adding OpenAPI spec will fail. Please refer to [OpenAPI Spec Doc](https://spec.openapis.org/oas/v3.1.0)
|
||||
</Note>
|
||||
@@ -5,18 +5,28 @@ title: Overview
|
||||
Embedchain comes with built-in support for various data sources. We handle the complexity of loading unstructured data from these data sources, allowing you to easily customize your app through a user-friendly interface.
|
||||
|
||||
<CardGroup cols={4}>
|
||||
<Card title="📊 csv" href="/data-sources/csv"></Card>
|
||||
<Card title="📚🌐 docs site" href="/data-sources/docs-site"></Card>
|
||||
<Card title="📊 CSV" href="/data-sources/csv"></Card>
|
||||
<Card title="📃 JSON" href="/data-sources/json"></Card>
|
||||
<Card title="📚 docs site" href="/data-sources/docs-site"></Card>
|
||||
<Card title="📄 docx" href="/data-sources/docx"></Card>
|
||||
<Card title="📝 mdx" href="/data-sources/mdx"></Card>
|
||||
<Card title="📓 notion" href="/data-sources/notion"></Card>
|
||||
<Card title="📰 pdf" href="/data-sources/pdf-file"></Card>
|
||||
<Card title="📓 Notion" href="/data-sources/notion"></Card>
|
||||
<Card title="📰 PDF" href="/data-sources/pdf-file"></Card>
|
||||
<Card title="❓💬 q&a pair" href="/data-sources/qna"></Card>
|
||||
<Card title="🗺️ sitemap" href="/data-sources/sitemap"></Card>
|
||||
<Card title="📝 text" href="/data-sources/text"></Card>
|
||||
<Card title="🌐📄 web page" href="/data-sources/web-page"></Card>
|
||||
<Card title="🌐 web page" href="/data-sources/web-page"></Card>
|
||||
<Card title="🧾 xml" href="/data-sources/xml"></Card>
|
||||
<Card title="🎥📺 youtube video" href="/data-sources/youtube-video"></Card>
|
||||
<Card title="🙌 OpenAPI" href="/data-sources/openapi"></Card>
|
||||
<Card title="📺 Youtube" href="/data-sources/youtube-video"></Card>
|
||||
<Card title="📬 Gmail" href="/data-sources/gmail"></Card>
|
||||
<Card title="🐘 Postgres" href="/data-sources/postgres"></Card>
|
||||
<Card title="🐬 MySQL" href="/data-sources/mysql"></Card>
|
||||
<Card title="🤖 Slack" href="/data-sources/slack"></Card>
|
||||
<Card title="🗨️ Discourse" href="/data-sources/discourse"></Card>
|
||||
<Card title="💬 Discord" href="/data-sources/discord"></Card>
|
||||
<Card title="📝 Github" href="/data-sources/github"></Card>
|
||||
<Card title="⚙️ Custom" href="/data-sources/custom"></Card>
|
||||
</CardGroup>
|
||||
|
||||
<br/ >
|
||||
|
||||
@@ -5,7 +5,7 @@ title: '📰 PDF file'
|
||||
To add any pdf file, use the data_type as `pdf_file`. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
|
||||
@@ -0,0 +1,64 @@
|
||||
---
|
||||
title: '🐘 Postgres'
|
||||
---
|
||||
|
||||
1. Setup the Postgres loader by configuring the postgres db.
|
||||
```Python
|
||||
from embedchain.loaders.postgres import PostgresLoader
|
||||
|
||||
config = {
|
||||
"host": "host_address",
|
||||
"port": "port_number",
|
||||
"dbname": "database_name",
|
||||
"user": "username",
|
||||
"password": "password",
|
||||
}
|
||||
|
||||
"""
|
||||
config = {
|
||||
"url": "your_postgres_url"
|
||||
}
|
||||
"""
|
||||
|
||||
postgres_loader = PostgresLoader(config=config)
|
||||
|
||||
```
|
||||
|
||||
You can either setup the loader by passing the postgresql url or by providing the config data.
|
||||
For more details on how to setup with valid url and config, check postgres [documentation](https://www.postgresql.org/docs/current/libpq-connect.html#LIBPQ-CONNSTRING:~:text=34.1.1.%C2%A0Connection%20Strings-,%23,-Several%20libpq%20functions).
|
||||
|
||||
NOTE: if you provide the `url` field in config, all other fields will be ignored.
|
||||
|
||||
2. Once you setup the loader, you can create an app and load data using the above postgres loader
|
||||
```Python
|
||||
import os
|
||||
from embedchain.pipeline import Pipeline as App
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "sk-xxx"
|
||||
|
||||
app = App()
|
||||
|
||||
question = "What is Elon Musk's networth?"
|
||||
response = app.query(question)
|
||||
# Answer: As of September 2021, Elon Musk's net worth is estimated to be around $250 billion, making him one of the wealthiest individuals in the world. However, please note that net worth can fluctuate over time due to various factors such as stock market changes and business ventures.
|
||||
|
||||
app.add("SELECT * FROM table_name;", data_type='postgres', loader=postgres_loader)
|
||||
# Adds `(1, 'What is your net worth, Elon Musk?', "As of October 2023, Elon Musk's net worth is $255.2 billion.")`
|
||||
|
||||
response = app.query(question)
|
||||
# Answer: As of October 2023, Elon Musk's net worth is $255.2 billion.
|
||||
```
|
||||
|
||||
NOTE: The `add` function of the app will accept any executable query to load data. DO NOT pass the `CREATE`, `INSERT` queries in `add` function as they will result in not adding any data, so it is pointless.
|
||||
|
||||
3. We automatically create a chunker to chunk your postgres data, however if you wish to provide your own chunker class. Here is how you can do that:
|
||||
```Python
|
||||
|
||||
from embedchain.chunkers.postgres import PostgresChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
|
||||
postgres_chunker_config = ChunkerConfig(chunk_size=1000, chunk_overlap=0, length_function=len)
|
||||
postgres_chunker = PostgresChunker(config=postgres_chunker_config)
|
||||
|
||||
app.add("SELECT * FROM table_name;", data_type='postgres', loader=postgres_loader, chunker=postgres_chunker)
|
||||
```
|
||||
@@ -5,7 +5,7 @@ title: '❓💬 Queston and answer pair'
|
||||
QnA pair is a local data type. To supply your own QnA pair, use the data_type as `qna_pair` and enter a tuple. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
|
||||
@@ -5,7 +5,7 @@ title: '🗺️ Sitemap'
|
||||
Add all web pages from an xml-sitemap. Filters non-text files. Use the data_type as `sitemap`. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
|
||||
@@ -0,0 +1,54 @@
|
||||
---
|
||||
title: '🤖 Slack'
|
||||
---
|
||||
|
||||
## Pre-requisite
|
||||
- Download required packages by running `pip install --upgrade "embedchain[slack]"`.
|
||||
- Configure your slack bot token as environment variable `SLACK_USER_TOKEN`.
|
||||
- Find your user token on your [Slack Account](https://api.slack.com/authentication/token-types)
|
||||
- Make sure your slack user token includes [search](https://api.slack.com/scopes/search:read) scope.
|
||||
|
||||
## Example
|
||||
1. Setup the Slack loader by configuring the Slack Webclient.
|
||||
```Python
|
||||
from embedchain.loaders.slack import SlackLoader
|
||||
|
||||
os.environ["SLACK_USER_TOKEN"] = "xoxp-*"
|
||||
|
||||
loader = SlackLoader()
|
||||
|
||||
"""
|
||||
config = {
|
||||
'base_url': slack_app_url,
|
||||
'headers': web_headers,
|
||||
'team_id': slack_team_id,
|
||||
}
|
||||
|
||||
loader = SlackLoader(config)
|
||||
"""
|
||||
```
|
||||
|
||||
NOTE: you can also pass the `config` with `base_url`, `headers`, `team_id` to setup your SlackLoader.
|
||||
|
||||
2. Once you setup the loader, you can create an app and load data using the above slack loader
|
||||
```Python
|
||||
import os
|
||||
from embedchain.pipeline import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
app.add("in:random", data_type="slack", loader=loader)
|
||||
question = "Which bots are available in the slack workspace's random channel?"
|
||||
# Answer: The available bot in the slack workspace's random channel is the Embedchain bot.
|
||||
```
|
||||
|
||||
3. We automatically create a chunker to chunk your slack data, however if you wish to provide your own chunker class. Here is how you can do that:
|
||||
```Python
|
||||
from embedchain.chunkers.slack import SlackChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
|
||||
slack_chunker_config = ChunkerConfig(chunk_size=1000, chunk_overlap=0, length_function=len)
|
||||
slack_chunker = SlackChunker(config=slack_chunker_config)
|
||||
|
||||
app.add(slack_chunker, data_type="slack", loader=loader, chunker=slack_chunker)
|
||||
```
|
||||
@@ -0,0 +1,16 @@
|
||||
---
|
||||
title: "📝 Substack"
|
||||
---
|
||||
|
||||
To add any Substack data sources to your app, just add the sitemap.xml of that url as the source and set the data_type to `substack`.
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
# source: for any substack just add the sitemap.xml url
|
||||
app.add('https://www.lennysnewsletter.com/sitemap.xml', data_type='substack')
|
||||
app.query("Who is Brian Chesky?")
|
||||
# Answer: Brian Chesky is the co-founder and CEO of Airbnb.
|
||||
```
|
||||
@@ -7,7 +7,7 @@ title: '📝 Text'
|
||||
Text is a local data type. To supply your own text, use the data_type as `text` and enter a string. The text is not processed, this can be very versatile. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
---
|
||||
title: '🌐📄 Web page'
|
||||
title: '🌐 Web page'
|
||||
---
|
||||
|
||||
To add any web page, use the data_type as `web_page`. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
|
||||
@@ -7,7 +7,7 @@ title: '🧾 XML file'
|
||||
To add any xml file, use the data_type as `xml`. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
|
||||
|
||||
@@ -1,12 +1,12 @@
|
||||
---
|
||||
title: '🎥📺 Youtube video'
|
||||
title: '📺 Youtube'
|
||||
---
|
||||
|
||||
|
||||
To add any youtube video to your app, use the data_type (first argument to `.add()` method) as `youtube_video`. Eg:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
app.add('a_valid_youtube_url_here', data_type='youtube_video')
|
||||
|
||||
@@ -1,91 +0,0 @@
|
||||
---
|
||||
title: '🌍 API Server'
|
||||
---
|
||||
|
||||
The API Server based on Flask integrates the `embedchain` package, offering endpoints to add, query, and chat to engage in conversations with a chatbot using JSON requests.
|
||||
|
||||
### 🐳 Docker Setup
|
||||
|
||||
- Open variables.env, and edit it to add your 🔑 `OPENAI_API_KEY`.
|
||||
- To setup your api server using docker, run the following command inside this folder using your terminal.
|
||||
|
||||
```bash
|
||||
docker-compose up --build
|
||||
```
|
||||
|
||||
📝 Note: The build command might take a while to install all the packages depending on your system resources.
|
||||
|
||||
### 🚀 Usage Instructions
|
||||
|
||||
- Your api server is running on [http://localhost:5000/](http://localhost:5000/)
|
||||
- To use the api server, make an api call to the endpoints `/add`, `/query` and `/chat` using the json formats discussed below.
|
||||
- To add data sources to the bot (/add):
|
||||
```json
|
||||
// Request
|
||||
{
|
||||
"data_type": "your_data_type_here",
|
||||
"url_or_text": "your_url_or_text_here"
|
||||
}
|
||||
|
||||
// Response
|
||||
{
|
||||
"data": "Added data_type: url_or_text"
|
||||
}
|
||||
```
|
||||
- To ask queries from the bot (/query):
|
||||
```json
|
||||
// Request
|
||||
{
|
||||
"question": "your_question_here"
|
||||
}
|
||||
|
||||
// Response
|
||||
{
|
||||
"data": "your_answer_here"
|
||||
}
|
||||
```
|
||||
- To chat with the bot (/chat):
|
||||
```json
|
||||
// Request
|
||||
{
|
||||
"question": "your_question_here"
|
||||
}
|
||||
|
||||
// Response
|
||||
{
|
||||
"data": "your_answer_here"
|
||||
}
|
||||
```
|
||||
|
||||
### 📡 Curl Call Formats
|
||||
|
||||
- To add data sources to the bot (/add):
|
||||
```bash
|
||||
curl -X POST \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"data_type": "your_data_type_here",
|
||||
"url_or_text": "your_url_or_text_here"
|
||||
}' \
|
||||
http://localhost:5000/add
|
||||
```
|
||||
- To ask queries from the bot (/query):
|
||||
```bash
|
||||
curl -X POST \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"question": "your_question_here"
|
||||
}' \
|
||||
http://localhost:5000/query
|
||||
```
|
||||
- To chat with the bot (/chat):
|
||||
```bash
|
||||
curl -X POST \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
"question": "your_question_here"
|
||||
}' \
|
||||
http://localhost:5000/chat
|
||||
```
|
||||
|
||||
🎉 Happy Chatting! 🎉
|
||||
@@ -1,5 +1,5 @@
|
||||
---
|
||||
title: '🤖 Discord Bot'
|
||||
title: "🤖 Discord Bot"
|
||||
---
|
||||
|
||||
### 🔑 Keys Setup
|
||||
@@ -12,9 +12,11 @@ title: '🤖 Discord Bot'
|
||||
- On the left sidebar, click on `OAuth2` and go to `General`.
|
||||
- Set `Authorization Method` to `In-app Authorization`. Under `Scopes` select `bot`.
|
||||
- Under `Bot Permissions` allow the following and then click on `Save Changes`.
|
||||
|
||||
```text
|
||||
Send Messages (under Text Permissions)
|
||||
```
|
||||
|
||||
- Now under `OAuth2` and go to `URL Generator`. Under `Scopes` select `bot`.
|
||||
- Under `Bot Permissions` set the same permissions as above.
|
||||
- Now scroll down and copy the `Generated URL`. Paste it in a browser window and select the Server where you want to add the bot.
|
||||
@@ -23,40 +25,46 @@ Send Messages (under Text Permissions)
|
||||
|
||||
### Take the bot online
|
||||
|
||||
1. Install embedchain python package:
|
||||
<Tabs>
|
||||
<Tab title="docker">
|
||||
```bash
|
||||
docker run --name discord-bot -e OPENAI_API_KEY=sk-xxx -e DISCORD_BOT_TOKEN=xxx -p 8080:8080 embedchain/discord-bot:latest
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="python">
|
||||
```bash
|
||||
pip install --upgrade "embedchain[discord]"
|
||||
|
||||
```bash
|
||||
pip install --upgrade "embedchain[discord]"
|
||||
```
|
||||
python -m embedchain.bots.discord
|
||||
|
||||
2. Launch your Discord bot:
|
||||
|
||||
|
||||
```bash
|
||||
python -m embedchain.bots.discord
|
||||
```
|
||||
|
||||
If you prefer to see the question and not only the answer, run it with
|
||||
|
||||
```bash
|
||||
python -m embedchain.bots.discord --include-question
|
||||
```
|
||||
# or if you prefer to see the question and not only the answer, run it with
|
||||
python -m embedchain.bots.discord --include-question
|
||||
```
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
### 🚀 Usage Instructions
|
||||
|
||||
- Go to the server where you have added your bot.
|
||||
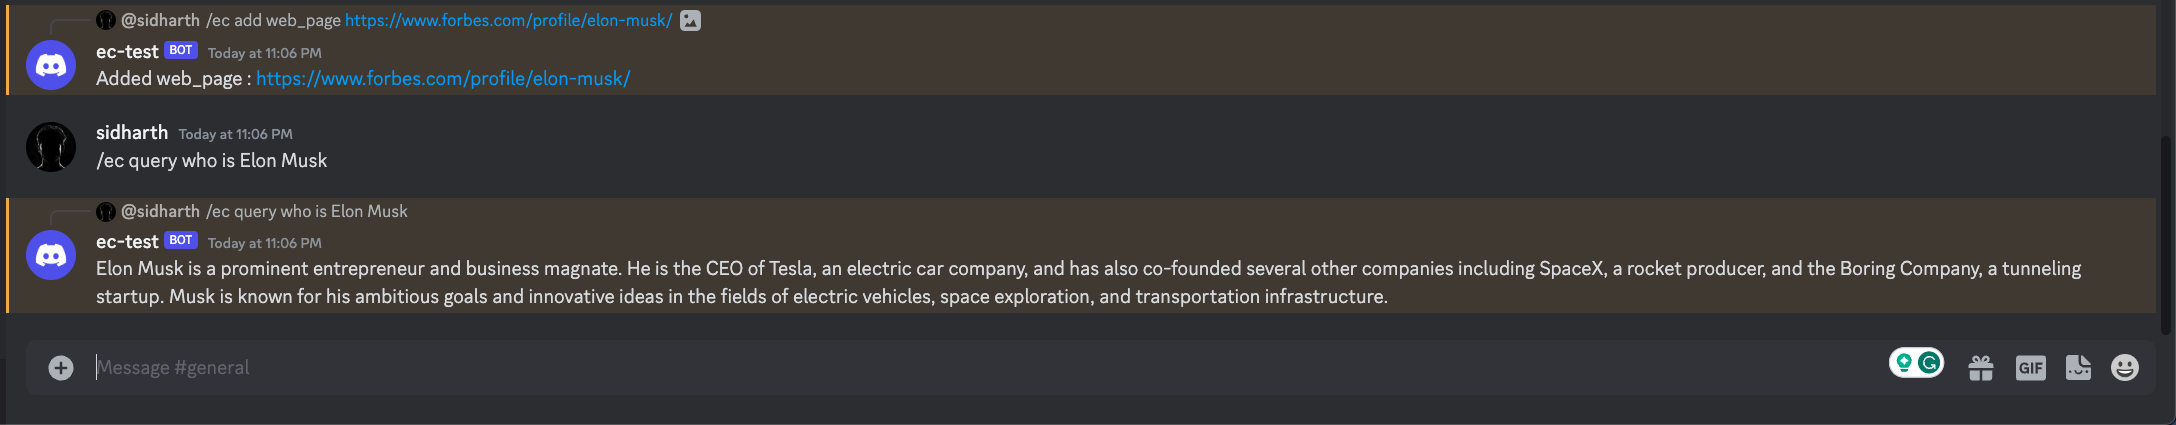
|
||||
- You can add data sources to the bot using the slash command:
|
||||
|
||||
```text
|
||||
/add <data_type> <url_or_text>
|
||||
/ec add <data_type> <url_or_text>
|
||||
```
|
||||
|
||||
- You can ask your queries from the bot using the slash command:
|
||||
|
||||
```text
|
||||
/query <question>
|
||||
/ec query <question>
|
||||
```
|
||||
|
||||
- You can chat with the bot using the slash command:
|
||||
|
||||
```text
|
||||
/chat <question>
|
||||
/ec chat <question>
|
||||
```
|
||||
|
||||
📝 Note: To use the bot privately, you can message the bot directly by right clicking the bot and selecting `Message`.
|
||||
|
||||
🎉 Happy Chatting! 🎉
|
||||
|
||||
@@ -2,16 +2,51 @@
|
||||
title: '🌐 Full Stack'
|
||||
---
|
||||
|
||||
The Full Stack app example can be found [here](https://github.com/embedchain/embedchain/tree/main/examples/full_stack).
|
||||
|
||||
This guide will help you setup the full stack app on your local machine.
|
||||
|
||||
### 🐳 Docker Setup
|
||||
|
||||
- To setup full stack app using docker, run the following command inside this folder using your terminal.
|
||||
- Create a `docker-compose.yml` file and paste the following code in it.
|
||||
|
||||
```yaml
|
||||
version: "3.9"
|
||||
|
||||
services:
|
||||
backend:
|
||||
container_name: embedchain-backend
|
||||
restart: unless-stopped
|
||||
build:
|
||||
context: backend
|
||||
dockerfile: Dockerfile
|
||||
image: embedchain/backend
|
||||
ports:
|
||||
- "8000:8000"
|
||||
|
||||
frontend:
|
||||
container_name: embedchain-frontend
|
||||
restart: unless-stopped
|
||||
build:
|
||||
context: frontend
|
||||
dockerfile: Dockerfile
|
||||
image: embedchain/frontend
|
||||
ports:
|
||||
- "3000:3000"
|
||||
depends_on:
|
||||
- "backend"
|
||||
```
|
||||
|
||||
- Run the following command,
|
||||
|
||||
```bash
|
||||
docker-compose up --build
|
||||
docker-compose up
|
||||
```
|
||||
|
||||
📝 Note: The build command might take a while to install all the packages depending on your system resources.
|
||||
|
||||
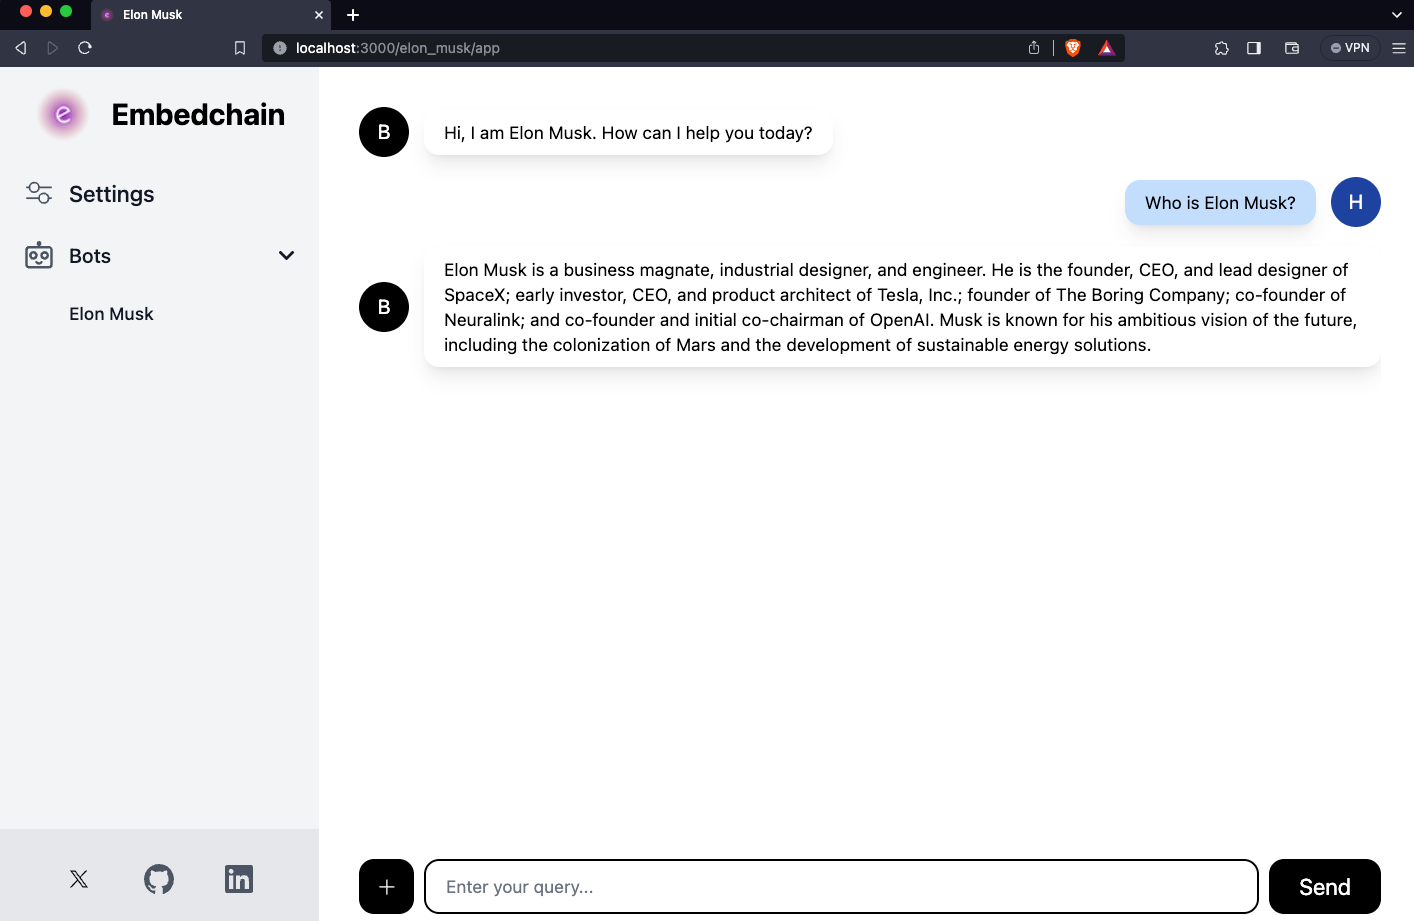
|
||||
|
||||
### 🚀 Usage Instructions
|
||||
|
||||
- Go to [http://localhost:3000/](http://localhost:3000/) in your browser to view the dashboard.
|
||||
|
||||
@@ -15,8 +15,21 @@ channels:read
|
||||
chat:write
|
||||
```
|
||||
5. Now select the option `Install to Workspace` and after it's done, copy the `Bot User OAuth Token` and set it in your secrets as `SLACK_BOT_TOKEN`.
|
||||
6. Run your bot now with `python3 -m embedchain.bots.slack`
|
||||
7. Expose your bot to the internet. Default port is `5000`, which can be changed by adding `port --8080` to the startup command. You can use your machine's public IP or DNS. Otherwise, employ a proxy server like [ngrok](https://ngrok.com/) to make your local bot accessible.
|
||||
6. Run your bot now,
|
||||
<Tabs>
|
||||
<Tab title="docker">
|
||||
```bash
|
||||
docker run --name slack-bot -e OPENAI_API_KEY=sk-xxx -e SLACK_BOT_TOKEN=xxx -p 8000:8000 embedchain/slack-bot
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="python">
|
||||
```bash
|
||||
pip install --upgrade "embedchain[slack]"
|
||||
python3 -m embedchain.bots.slack --port 8000
|
||||
```
|
||||
</Tab>
|
||||
</Tabs>
|
||||
7. Expose your bot to the internet. You can use your machine's public IP or DNS. Otherwise, employ a proxy server like [ngrok](https://ngrok.com/) to make your local bot accessible.
|
||||
8. On the Slack API website go to `Event Subscriptions` on the left Sidebar and turn on `Enable Events`.
|
||||
9. In `Request URL`, enter your server or ngrok address.
|
||||
10. After it gets verified, click on `Subscribe to bot events`, add `message.channels` Bot User Event and click on `Save Changes`.
|
||||
|
||||
@@ -1,21 +1,46 @@
|
||||
---
|
||||
title: '📱 Telegram Bot'
|
||||
title: "📱 Telegram Bot"
|
||||
---
|
||||
|
||||
### 🖼️ Template Setup
|
||||
|
||||
- Fork [this](https://replit.com/@taranjeetio/EC-Telegram-Bot-Template?v=1#README.md) replit template.
|
||||
- Set your `OPENAI_API_KEY` in Secrets.
|
||||
- Open the Telegram app and search for the `BotFather` user.
|
||||
- Start a chat with BotFather and use the `/newbot` command to create a new bot.
|
||||
- Follow the instructions to choose a name and username for your bot.
|
||||
- Once the bot is created, BotFather will provide you with a unique token for your bot.
|
||||
- Set this token as `TELEGRAM_BOT_TOKEN` in Secrets.
|
||||
|
||||
<Tabs>
|
||||
<Tab title="docker">
|
||||
```bash
|
||||
docker run --name telegram-bot -e OPENAI_API_KEY=sk-xxx -e TELEGRAM_BOT_TOKEN=xxx -p 8000:8000 embedchain/telegram-bot
|
||||
```
|
||||
|
||||
<Note>
|
||||
If you wish to use **Docker**, you would need to host your bot on a server.
|
||||
You can use [ngrok](https://ngrok.com/) to expose your localhost to the
|
||||
internet and then set the webhook using the ngrok URL.
|
||||
</Note>
|
||||
|
||||
</Tab>
|
||||
<Tab title="replit">
|
||||
<Card>
|
||||
Fork <ins>**[this](https://replit.com/@taranjeetio/EC-Telegram-Bot-Template?v=1#README.md)**</ins> replit template.
|
||||
</Card>
|
||||
|
||||
- Set your `OPENAI_API_KEY` in Secrets.
|
||||
- Set the unique token as `TELEGRAM_BOT_TOKEN` in Secrets.
|
||||
|
||||
</Tab>
|
||||
|
||||
</Tabs>
|
||||
|
||||
- Click on `Run` in the replit container and a URL will get generated for your bot.
|
||||
- Now set your webhook by running the following link in your browser:
|
||||
|
||||
```url
|
||||
https://api.telegram.org/bot<Your_Telegram_Bot_Token>/setWebhook?url=<Replit_Generated_URL>
|
||||
```
|
||||
|
||||
- When you get a successful response in your browser, your bot is ready to be used.
|
||||
|
||||
### 🚀 Usage Instructions
|
||||
|
||||
@@ -12,10 +12,19 @@ pip install --upgrade embedchain
|
||||
|
||||
2. Launch your WhatsApp bot:
|
||||
|
||||
<Tabs>
|
||||
<Tab title="docker">
|
||||
```bash
|
||||
docker run --name whatsapp-bot -e OPENAI_API_KEY=sk-xxx -p 8000:8000 embedchain/whatsapp-bot
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="python">
|
||||
```bash
|
||||
python -m embedchain.bots.whatsapp --port 5000
|
||||
```
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
```bash
|
||||
python -m embedchain.bots.whatsapp --port 5000
|
||||
```
|
||||
|
||||
If your bot needs to be accessible online, use your machine's public IP or DNS. Otherwise, employ a proxy server like [ngrok](https://ngrok.com/) to make your local bot accessible.
|
||||
|
||||
|
||||

|
Before Width: | Height: | Size: 70 KiB After Width: | Height: | Size: 5.0 KiB |
@@ -0,0 +1,130 @@
|
||||
---
|
||||
title: 🔎 Examples
|
||||
---
|
||||
|
||||
# Explore awesome apps
|
||||
|
||||
Check out the remarkable work accomplished using [Embedchain](https://app.embedchain.ai/custom-gpts/).
|
||||
|
||||
## Collection of Google colab notebook and Replit links for users
|
||||
|
||||
Get started with Embedchain by trying out the examples below. You can run the examples in your browser using Google Colab or Replit.
|
||||
|
||||
<table>
|
||||
<thead>
|
||||
<tr>
|
||||
<th>LLM</th>
|
||||
<th>Google Colab</th>
|
||||
<th>Replit</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td className="align-middle">OpenAI</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/openai.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/openai#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Anthropic</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/anthropic.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/anthropic#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Azure OpenAI</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/azure-openai.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/azureopenai#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">VertexAI</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/vertex_ai.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/vertexai#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Cohere</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/cohere.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/cohere#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Hugging Face</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/hugging_face_hub.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/huggingface#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">JinaChat</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/jina.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/jina#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">GPT4All</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/gpt4all.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/gpt4all#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Llama2</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/llama2.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/llama2#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
<table>
|
||||
<thead>
|
||||
<tr>
|
||||
<th>Embedding model</th>
|
||||
<th>Google Colab</th>
|
||||
<th>Replit</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td className="align-middle">OpenAI</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/openai.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/openai#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">VertexAI</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/vertex_ai.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/vertexai#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">GPT4All</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/gpt4all.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/gpt4all#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Hugging Face</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/hugging_face_hub.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/huggingface#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
<table>
|
||||
<thead>
|
||||
<tr>
|
||||
<th>Vector DB</th>
|
||||
<th>Google Colab</th>
|
||||
<th>Replit</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
<tr>
|
||||
<td className="align-middle">ChromaDB</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/chromadb.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/chromadb#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Elasticsearch</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/elasticsearch.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/elasticsearchdb#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Opensearch</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/opensearch.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/opensearchdb#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td className="align-middle">Pinecone</td>
|
||||
<td className="align-middle"><a target="_blank" href="https://colab.research.google.com/github/embedchain/embedchain/blob/main/notebooks/pinecone.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" noZoom alt="Open In Colab"/></a></td>
|
||||
<td className="align-middle"><a target="_blank" href="https://replit.com/@taranjeetio/pineconedb#main.py"><img src="https://replit.com/badge?caption=Try%20with%20Replit&variant=small" noZoom alt="Try with Replit Badge"/></a></td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
@@ -2,26 +2,78 @@
|
||||
title: ❓ FAQs
|
||||
description: 'Collections of all the frequently asked questions'
|
||||
---
|
||||
<AccordionGroup>
|
||||
<Accordion title="Does Embedchain support OpenAI's Assistant APIs?">
|
||||
Yes, it does. Please refer to the [OpenAI Assistant docs page](/get-started/openai-assistant).
|
||||
</Accordion>
|
||||
<Accordion title="How to use MistralAI language model?">
|
||||
Use the model provided on huggingface: `mistralai/Mistral-7B-v0.1`
|
||||
<CodeGroup>
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
#### How to use GPT-4 as the LLM model?
|
||||
os.environ["OPENAI_API_KEY"] = "sk-xxx"
|
||||
os.environ["HUGGINGFACE_ACCESS_TOKEN"] = "hf_your_token"
|
||||
|
||||
app = App.from_config("huggingface.yaml")
|
||||
```
|
||||
```yaml huggingface.yaml
|
||||
llm:
|
||||
provider: huggingface
|
||||
config:
|
||||
model: 'mistralai/Mistral-7B-v0.1'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 0.5
|
||||
stream: false
|
||||
```
|
||||
</CodeGroup>
|
||||
</Accordion>
|
||||
<Accordion title="How to use ChatGPT 4 turbo model released on OpenAI DevDay?">
|
||||
Use the model `gpt-4-turbo` provided my openai.
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ['OPENAI_API_KEY'] = 'xxx'
|
||||
|
||||
# load llm configuration from gpt4_turbo.yaml file
|
||||
app = App.from_config(config_path="gpt4_turbo.yaml")
|
||||
```
|
||||
|
||||
```yaml gpt4_turbo.yaml
|
||||
llm:
|
||||
provider: openai
|
||||
config:
|
||||
model: 'gpt-4-turbo'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
stream: false
|
||||
```
|
||||
</CodeGroup>
|
||||
</Accordion>
|
||||
<Accordion title="How to use GPT-4 as the LLM model?">
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ['OPENAI_API_KEY'] = 'xxx'
|
||||
|
||||
# load llm configuration from gpt4.yaml file
|
||||
app = App.from_config(yaml_path="gpt4.yaml")
|
||||
app = App.from_config(config_path="gpt4.yaml")
|
||||
```
|
||||
|
||||
```yaml gpt4.yaml
|
||||
llm:
|
||||
provider: openai
|
||||
model: 'gpt-4'
|
||||
config:
|
||||
model: 'gpt-4'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -29,26 +81,25 @@ llm:
|
||||
```
|
||||
|
||||
</CodeGroup>
|
||||
|
||||
#### I don't have OpenAI credits. How can I use some open source model?
|
||||
|
||||
</Accordion>
|
||||
<Accordion title="I don't have OpenAI credits. How can I use some open source model?">
|
||||
<CodeGroup>
|
||||
|
||||
```python main.py
|
||||
import os
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
os.environ['OPENAI_API_KEY'] = 'xxx'
|
||||
|
||||
# load llm configuration from opensource.yaml file
|
||||
app = App.from_config(yaml_path="opensource.yaml")
|
||||
app = App.from_config(config_path="opensource.yaml")
|
||||
```
|
||||
|
||||
```yaml opensource.yaml
|
||||
llm:
|
||||
provider: gpt4all
|
||||
model: 'orca-mini-3b.ggmlv3.q4_0.bin'
|
||||
config:
|
||||
model: 'orca-mini-3b-gguf2-q4_0.gguf'
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
@@ -61,8 +112,10 @@ embedder:
|
||||
```
|
||||
</CodeGroup>
|
||||
|
||||
#### How to contact support?
|
||||
</Accordion>
|
||||
</AccordionGroup>
|
||||
|
||||
#### Need more help?
|
||||
If docs aren't sufficient, please feel free to reach out to us using one of the following methods:
|
||||
|
||||
<Snippet file="get-help.mdx" />
|
||||
|
||||
@@ -3,33 +3,109 @@ title: 📚 Introduction
|
||||
description: '📝 Embedchain is a Data Platform for LLMs - load, index, retrieve, and sync any unstructured data'
|
||||
---
|
||||
|
||||
## 🤔 What is Embedchain?
|
||||
## 🌐 What is Embedchain?
|
||||
|
||||
Embedchain abstracts the entire process of loading data, chunking it, creating embeddings, and storing it in a vector database.
|
||||
Embedchain simplifies data handling by automatically processing unstructured data, breaking it into chunks, generating embeddings, and storing it in a vector database.
|
||||
|
||||
You can add data from different data sources using the `.add()` method. Then, simply use the `.query()` method to find answers from the added datasets.
|
||||
Through various APIs, you can obtain contextual information for queries, find answers to specific questions, and engage in chat conversations using your data.
|
||||
## 🔍 Search
|
||||
|
||||
If you want to create a Naval Ravikant bot with a YouTube video, a book in PDF format, two blog posts, and a question and answer pair, all you need to do is add the respective links. Embedchain will take care of the rest, creating a bot for you.
|
||||
Embedchain lets you get most relevant context by doing semantic search over your data sources for a provided query. See the example below:
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
naval_bot = App()
|
||||
# Add online data
|
||||
naval_bot.add("https://www.youtube.com/watch?v=3qHkcs3kG44")
|
||||
naval_bot.add("https://navalmanack.s3.amazonaws.com/Eric-Jorgenson_The-Almanack-of-Naval-Ravikant_Final.pdf")
|
||||
naval_bot.add("https://nav.al/feedback")
|
||||
naval_bot.add("https://nav.al/agi")
|
||||
naval_bot.add("The Meanings of Life", 'text', metadata={'chapter': 'philosphy'})
|
||||
# Initialize app
|
||||
app = App()
|
||||
|
||||
# Add local resources
|
||||
naval_bot.add(("Who is Naval Ravikant?", "Naval Ravikant is an Indian-American entrepreneur and investor."))
|
||||
# Add data source
|
||||
app.add("https://www.forbes.com/profile/elon-musk")
|
||||
|
||||
naval_bot.query("What unique capacity does Naval argue humans possess when it comes to understanding explanations or concepts?")
|
||||
# Answer: Naval argues that humans possess the unique capacity to understand explanations or concepts to the maximum extent possible in this physical reality.
|
||||
# Get relevant context using semantic search
|
||||
context = app.search("What is the net worth of Elon?", num_documents=2)
|
||||
print(context)
|
||||
# Context:
|
||||
# [
|
||||
# {
|
||||
# 'context': 'Elon Musk PROFILEElon MuskCEO, Tesla$221.9BReal Time Net Worthas of 10/29/23Reflects change since 5 pm ET of prior trading day. 1 in the world todayPhoto by Martin Schoeller for ForbesAbout Elon MuskElon Musk cofounded six companies, including electric car maker Tesla, rocket producer SpaceX and tunneling startup Boring Company.He owns about 21% of Tesla between stock and options, but has pledged more than half his shares as collateral for personal loans of up to $3.5 billion.SpaceX, founded in',
|
||||
# 'source': 'https://www.forbes.com/profile/elon-musk',
|
||||
# 'document_id': 'some_document_id'
|
||||
# },
|
||||
# {
|
||||
# 'context': 'company, which is now called X.Wealth HistoryHOVER TO REVEAL NET WORTH BY YEARForbes Lists 1Forbes 400 (2023)The Richest Person In Every State (2023) 2Billionaires (2023) 1Innovative Leaders (2019) 25Powerful People (2018) 12Richest In Tech (2017)Global Game Changers (2016)More ListsPersonal StatsAge52Source of WealthTesla, SpaceX, Self MadeSelf-Made Score8Philanthropy Score1ResidenceAustin, TexasCitizenshipUnited StatesMarital StatusSingleChildren11EducationBachelor of Arts/Science, University',
|
||||
# 'source': 'https://www.forbes.com/profile/elon-musk',
|
||||
# 'document_id': 'some_document_id'
|
||||
# }
|
||||
# ]
|
||||
```
|
||||
|
||||
## 🚀 How it works?
|
||||
## ❓Query
|
||||
|
||||
Embedchain empowers developers to ask questions and receive relevant answers through a user-friendly query API. Refer to the following example to learn how to utilize the query API:
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# Initialize app
|
||||
app = App()
|
||||
|
||||
# Add data source
|
||||
app.add("https://www.forbes.com/profile/elon-musk")
|
||||
|
||||
# Get relevant answer for your query
|
||||
answer = app.query("What is the net worth of Elon?")
|
||||
print(answer)
|
||||
# Answer: The net worth of Elon Musk is $221.9 billion.
|
||||
```
|
||||
|
||||
## 💬 Chat
|
||||
|
||||
Embedchain allows easy chatting over your data sources using a user-friendly chat API. Check out the example below to understand how to use the chat API:
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# Initialize app
|
||||
app = App()
|
||||
|
||||
# Add data source
|
||||
app.add("https://www.forbes.com/profile/elon-musk")
|
||||
|
||||
# Chat on your data using `.chat()`
|
||||
answer = app.chat("How much did Elon pay for Twitter?")
|
||||
print(answer)
|
||||
# Answer: Elon Musk paid $44 billion for Twitter.
|
||||
```
|
||||
|
||||
## 🚀 Deploy
|
||||
|
||||
Embedchain enables developers to deploy their LLM-powered apps in production using the Embedchain platform. The platform offers free access to context on your data through its REST API. Once the pipeline is deployed, you can update your data sources anytime after deployment.
|
||||
|
||||
See the example below on how to use the deploy API:
|
||||
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
# Initialize app
|
||||
app = App()
|
||||
|
||||
# Add data source
|
||||
app.add("https://www.forbes.com/profile/elon-musk")
|
||||
|
||||
# Deploy your pipeline to Embedchain Platform
|
||||
app.deploy()
|
||||
|
||||
# 🔑 Enter your Embedchain API key. You can find the API key at https://app.embedchain.ai/settings/keys/
|
||||
# ec-xxxxxx
|
||||
|
||||
# 🛠️ Creating pipeline on the platform...
|
||||
# 🎉🎉🎉 Pipeline created successfully! View your pipeline: https://app.embedchain.ai/pipelines/xxxxx
|
||||
|
||||
# 🛠️ Adding data to your pipeline...
|
||||
# ✅ Data of type: web_page, value: https://www.forbes.com/profile/elon-musk added successfully.
|
||||
```
|
||||
|
||||
## 🛠️ How it works?
|
||||
|
||||
Embedchain abstracts out the following steps from you to easily create LLM powered apps:
|
||||
|
||||
@@ -53,3 +129,5 @@ The process of loading the dataset and querying involves multiple steps, each wi
|
||||
- How should I find similar documents for a query? Which ranking model should I use?
|
||||
|
||||
Embedchain takes care of all these nuances and provides a simple interface to create apps on any data.
|
||||
|
||||
## [🚀 Get started](https://docs.embedchain.ai/get-started/quickstart)
|
||||
|
||||
@@ -0,0 +1,95 @@
|
||||
---
|
||||
title: '🤖 OpenAI Assistant'
|
||||
---
|
||||
|
||||
<img src="https://blogs.swarthmore.edu/its/wp-content/uploads/2022/05/openai.jpg" align="center" width="500" alt="OpenAI Logo"/>
|
||||
|
||||
Embedchain now supports [OpenAI Assistants API](https://platform.openai.com/docs/assistants/overview) which allows you to build AI assistants within your own applications. An Assistant has instructions and can leverage models, tools, and knowledge to respond to user queries.
|
||||
|
||||
At a high level, an integration of the Assistants API has the following flow:
|
||||
|
||||
1. Create an Assistant in the API by defining custom instructions and picking a model
|
||||
2. Create a Thread when a user starts a conversation
|
||||
3. Add Messages to the Thread as the user ask questions
|
||||
4. Run the Assistant on the Thread to trigger responses. This automatically calls the relevant tools.
|
||||
|
||||
Creating an OpenAI Assistant using Embedchain is very simple 3 step process.
|
||||
|
||||
## Step 1: Create OpenAI Assistant
|
||||
|
||||
Make sure that you have `OPENAI_API_KEY` set in the environment variable.
|
||||
|
||||
```python Initialize
|
||||
from embedchain.store.assistants import OpenAIAssistant
|
||||
|
||||
assistant = OpenAIAssistant(
|
||||
name="OpenAI DevDay Assistant",
|
||||
instructions="You are an organizer of OpenAI DevDay",
|
||||
)
|
||||
```
|
||||
|
||||
If you want to use the existing assistant, you can do something like this:
|
||||
|
||||
```python Initialize
|
||||
# Load an assistant and create a new thread
|
||||
assistant = OpenAIAssistant(assistant_id="asst_xxx")
|
||||
|
||||
# Load a specific thread for an assistant
|
||||
assistant = OpenAIAssistant(assistant_id="asst_xxx", thread_id="thread_xxx")
|
||||
```
|
||||
|
||||
### Arguments
|
||||
|
||||
<ResponseField name="name" type="string">
|
||||
Name for your AI assistant
|
||||
</ResponseField>
|
||||
|
||||
<ResponseField name="instructions" type="string">
|
||||
how the Assistant and model should behave or respond
|
||||
</ResponseField>
|
||||
|
||||
<ResponseField name="assistant_id" type="string">
|
||||
Load existing OpenAI Assistant. If you pass this, you don't have to pass other arguments.
|
||||
</ResponseField>
|
||||
|
||||
<ResponseField name="thread_id" type="string">
|
||||
Existing OpenAI thread id if exists
|
||||
</ResponseField>
|
||||
|
||||
<ResponseField name="model" type="str" default="gpt-4-1106-preview">
|
||||
OpenAI model to use
|
||||
</ResponseField>
|
||||
|
||||
<ResponseField name="tools" type="list">
|
||||
OpenAI tools to use. Default set to `[{"type": "retrieval"}]`
|
||||
</ResponseField>
|
||||
|
||||
<ResponseField name="data_sources" type="list" default="[]">
|
||||
Add data sources to your assistant. You can add in the following format: `[{"source": "https://example.com", "data_type": "web_page"}]`
|
||||
</ResponseField>
|
||||
|
||||
<ResponseField name="telemetry" type="boolean" default="True">
|
||||
Anonymous telemetry (doesn't collect any user information or user's files). Used to improve the Embedchain package utilization. Default is `True`.
|
||||
</ResponseField>
|
||||
|
||||
## Step-2: Add data to thread
|
||||
|
||||
You can add any custom data source that is supported by Embedchain. Else, you can directly pass the file path on your local system and Embedchain propagates it to OpenAI Assistant.
|
||||
```python Add data
|
||||
assistant.add("/path/to/file.pdf")
|
||||
assistant.add("https://www.youtube.com/watch?v=U9mJuUkhUzk")
|
||||
assistant.add("https://openai.com/blog/new-models-and-developer-products-announced-at-devday")
|
||||
```
|
||||
|
||||
## Step-3: Chat with your Assistant
|
||||
```python Chat
|
||||
assistant.chat("How much OpenAI credits were offered to attendees during OpenAI DevDay?")
|
||||
# Response: 'Every attendee of OpenAI DevDay 2023 was offered $500 in OpenAI credits.'
|
||||
```
|
||||
|
||||
You can try it out yourself using the following Google Colab notebook:
|
||||
|
||||
<a href="https://colab.research.google.com/drive/1BKlXZYSl6AFRgiHZ5XIzXrXC_24kDYHQ?usp=sharing">
|
||||
<img src="https://camo.githubusercontent.com/84f0493939e0c4de4e6dbe113251b4bfb5353e57134ffd9fcab6b8714514d4d1/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open in Colab" />
|
||||
</a>
|
||||
|
||||
@@ -11,48 +11,86 @@ Install embedchain python package:
|
||||
pip install embedchain
|
||||
```
|
||||
|
||||
<Tip>
|
||||
Embedchain now supports OpenAI's latest `gpt-4-turbo` model. Checkout the [FAQs](/get-started/faq#how-to-use-gpt-4-turbo-model-released-on-openai-devday).
|
||||
</Tip>
|
||||
|
||||
Creating an app involves 3 steps:
|
||||
|
||||
<Steps>
|
||||
<Step title="⚙️ Import app instance">
|
||||
```python
|
||||
from embedchain import App
|
||||
app = App()
|
||||
```
|
||||
```python
|
||||
from embedchain import Pipeline as App
|
||||
app = App()
|
||||
```
|
||||
<Accordion title="Customize your app by a simple YAML config" icon="gear-complex">
|
||||
Embedchain provides a wide range of options to customize your app. You can customize the model, data sources, and much more.
|
||||
Explore the custom configurations [here](https://docs.embedchain.ai/advanced/configuration).
|
||||
<CodeGroup>
|
||||
```python yaml_app.py
|
||||
from embedchain import Pipeline as App
|
||||
app = App.from_config(config_path="config.yaml")
|
||||
```
|
||||
```python json_app.py
|
||||
from embedchain import Pipeline as App
|
||||
app = App.from_config(config_path="config.json")
|
||||
```
|
||||
```python app.py
|
||||
from embedchain import Pipeline as App
|
||||
config = {} # Add your config here
|
||||
app = App.from_config(config=config)
|
||||
```
|
||||
</CodeGroup>
|
||||
</Accordion>
|
||||
</Step>
|
||||
<Step title="🗃️ Add data sources">
|
||||
```python
|
||||
# Add different data sources
|
||||
elon_bot.add("https://en.wikipedia.org/wiki/Elon_Musk")
|
||||
elon_bot.add("https://www.forbes.com/profile/elon-musk")
|
||||
# You can also add local data sources such as pdf, csv files etc.
|
||||
# elon_bot.add("/path/to/file.pdf")
|
||||
```
|
||||
```python
|
||||
app.add("https://en.wikipedia.org/wiki/Elon_Musk")
|
||||
app.add("https://www.forbes.com/profile/elon-musk")
|
||||
# app.add("path/to/file/elon_musk.pdf")
|
||||
```
|
||||
<Accordion title="Embedchain supports adding data from many data sources." icon="files">
|
||||
Embedchain supports adding data from many data sources including web pages, PDFs, databases, and more.
|
||||
Explore the list of supported [data sources](https://docs.embedchain.ai/data-sources/overview).
|
||||
</Accordion>
|
||||
</Step>
|
||||
<Step title="💬 Query or chat on your data and get answers">
|
||||
```python
|
||||
elon_bot.query("What is the net worth of Elon Musk today?")
|
||||
# Answer: The net worth of Elon Musk today is $258.7 billion.
|
||||
```
|
||||
<Step title="💬 Ask questions, chat, or search through your data with ease">
|
||||
```python
|
||||
app.query("What is the net worth of Elon Musk today?")
|
||||
# Answer: The net worth of Elon Musk today is $258.7 billion.
|
||||
```
|
||||
<Accordion title="Want to chat with your app?" icon="face-thinking">
|
||||
Embedchain provides a wide range of features to interact with your app. You can chat with your app, ask questions, search through your data, and much more.
|
||||
```python
|
||||
app.chat("How many companies does Elon Musk run? Name those")
|
||||
# Answer: Elon Musk runs 3 companies: Tesla, SpaceX, and Neuralink.
|
||||
app.chat("What is his net worth today?")
|
||||
# Answer: The net worth of Elon Musk today is $258.7 billion.
|
||||
```
|
||||
To learn about other features, click [here](https://docs.embedchain.ai/get-started/introduction)
|
||||
</Accordion>
|
||||
</Step>
|
||||
<Step title="🚀 Seamlessly launch your App on the Embedchain Platform!">
|
||||
```python
|
||||
app.deploy()
|
||||
# 🔑 Enter your Embedchain API key. You can find the API key at https://app.embedchain.ai/settings/keys/
|
||||
# ec-xxxxxx
|
||||
|
||||
# 🛠️ Creating pipeline on the platform...
|
||||
# 🎉🎉🎉 Pipeline created successfully! View your pipeline: https://app.embedchain.ai/pipelines/xxxxx
|
||||
|
||||
# 🛠️ Adding data to your pipeline...
|
||||
# ✅ Data of type: web_page, value: https://www.forbes.com/profile/elon-musk added successfully.
|
||||
```
|
||||
<Accordion title="Share your app with others" icon="laptop-mobile">
|
||||
You can now share your app with others from our platform.
|
||||
Access your app on our [platform](https://app.embedchain.ai/).
|
||||
</Accordion>
|
||||
</Step>
|
||||
</Steps>
|
||||
|
||||
Putting it together, you can run your first app using the following code. Make sure to set the `OPENAI_API_KEY` 🔑 environment variable in the code.
|
||||
Putting it together, you can run your first app using the following Google Colab. Make sure to set the `OPENAI_API_KEY` 🔑 environment variable in the code.
|
||||
|
||||
```python
|
||||
import os
|
||||
from embedchain import App
|
||||
|
||||
os.environ["OPENAI_API_KEY"] = "xxx"
|
||||
elon_bot = App()
|
||||
|
||||
# Add different data sources
|
||||
elon_bot.add("https://en.wikipedia.org/wiki/Elon_Musk")
|
||||
elon_bot.add("https://www.forbes.com/profile/elon-musk")
|
||||
# You can also add local data sources such as pdf, csv files etc.
|
||||
# elon_bot.add("/path/to/file.pdf")
|
||||
|
||||
response = elon_bot.query("What is the net worth of Elon Musk today?")
|
||||
print(response)
|
||||
# Answer: The net worth of Elon Musk today is $258.7 billion.
|
||||
```
|
||||
<a href="https://colab.research.google.com/drive/17ON1LPonnXAtLaZEebnOktstB_1cJJmh?usp=sharing">
|
||||
<img src="https://camo.githubusercontent.com/84f0493939e0c4de4e6dbe113251b4bfb5353e57134ffd9fcab6b8714514d4d1/68747470733a2f2f636f6c61622e72657365617263682e676f6f676c652e636f6d2f6173736574732f636f6c61622d62616467652e737667" alt="Open in Colab" />
|
||||
</a>
|
||||
|
||||

|
Before Width: | Height: | Size: 256 KiB |

|
After Width: | Height: | Size: 8.2 MiB |

|
After Width: | Height: | Size: 83 KiB |
@@ -39,7 +39,7 @@ os.environ['LANGCHAIN_PROJECT] = <your-project>
|
||||
|
||||
|
||||
```python
|
||||
from embedchain import App
|
||||
from embedchain import Pipeline as App
|
||||
|
||||
app = App()
|
||||
app.add("https://en.wikipedia.org/wiki/Elon_Musk")
|
||||
|
||||

|
Before Width: | Height: | Size: 42 KiB After Width: | Height: | Size: 3.1 KiB |

|
Before Width: | Height: | Size: 42 KiB After Width: | Height: | Size: 3.1 KiB |
@@ -3,40 +3,70 @@
|
||||
"name": "Embedchain",
|
||||
"logo": {
|
||||
"dark": "/logo/dark.svg",
|
||||
"light": "/logo/light.svg"
|
||||
"light": "/logo/light.svg",
|
||||
"href": "https://embedchain.ai/"
|
||||
},
|
||||
"favicon": "/favicon.png",
|
||||
"colors": {
|
||||
"primary": "#12A7D3",
|
||||
"light": "#81D7F7",
|
||||
"dark": "#004E7A"
|
||||
"primary": "#3B2FC9",
|
||||
"light": "#6673FF",
|
||||
"dark": "#3B2FC9",
|
||||
"background": {
|
||||
"dark": "#0f1117",
|
||||
"light": "#fff"
|
||||
}
|
||||
},
|
||||
"modeToggle": {
|
||||
"default": "dark"
|
||||
},
|
||||
"openapi": ["/rest-api.json"],
|
||||
"metadata": {
|
||||
"og:image": "/images/og.png",
|
||||
"twitter:site": "@embedchain"
|
||||
},
|
||||
"anchors": [
|
||||
{
|
||||
"name": "Embedchain Platform",
|
||||
"icon": "tv",
|
||||
"url": "https://app.embedchain.ai/"
|
||||
},
|
||||
{
|
||||
"name": "Join our slack",
|
||||
"icon": "slack",
|
||||
"url": "https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw"
|
||||
}
|
||||
],
|
||||
"topbarLinks": [
|
||||
{
|
||||
"name": "Twitter",
|
||||
"url": "https://twitter.com/embedchain"
|
||||
},
|
||||
{
|
||||
"name":"Slack",
|
||||
"url":"https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw"
|
||||
},
|
||||
{
|
||||
"name": "Discord",
|
||||
"url": "https://discord.gg/6PzXDgEjG5"
|
||||
"name": "Create account",
|
||||
"url": "https://app.embedchain.ai/login/"
|
||||
}
|
||||
],
|
||||
"topbarCtaButton": {
|
||||
"name": "GitHub",
|
||||
"url": "https://embedchain.ai"
|
||||
"name": "Get started",
|
||||
"url": "https://app.embedchain.ai"
|
||||
},
|
||||
"primaryTab": {
|
||||
"name": "Docs"
|
||||
},
|
||||
"navigation": [
|
||||
{
|
||||
"group": "Get started",
|
||||
"pages": ["get-started/quickstart", "get-started/introduction", "get-started/faq"]
|
||||
"pages": [
|
||||
"get-started/quickstart",
|
||||
"get-started/introduction",
|
||||
"get-started/openai-assistant",
|
||||
"get-started/faq",
|
||||
"get-started/examples"
|
||||
]
|
||||
},
|
||||
{
|
||||
"group": "Components",
|
||||
"pages": ["components/llms", "components/embedding-models", "components/vector-databases"]
|
||||
"pages": [
|
||||
"components/llms",
|
||||
"components/embedding-models",
|
||||
"components/vector-databases"
|
||||
]
|
||||
},
|
||||
{
|
||||
"group": "Data sources",
|
||||
@@ -46,6 +76,7 @@
|
||||
"group": "Supported data sources",
|
||||
"pages": [
|
||||
"data-sources/csv",
|
||||
"data-sources/json",
|
||||
"data-sources/docs-site",
|
||||
"data-sources/docx",
|
||||
"data-sources/mdx",
|
||||
@@ -55,7 +86,11 @@
|
||||
"data-sources/sitemap",
|
||||
"data-sources/text",
|
||||
"data-sources/web-page",
|
||||
"data-sources/youtube-video"
|
||||
"data-sources/openapi",
|
||||
"data-sources/youtube-video",
|
||||
"data-sources/discourse",
|
||||
"data-sources/substack",
|
||||
"data-sources/discord"
|
||||
]
|
||||
},
|
||||
"data-sources/data-type-handling"
|
||||
@@ -66,15 +101,33 @@
|
||||
"pages": ["advanced/configuration"]
|
||||
},
|
||||
{
|
||||
"group": "Examples",
|
||||
"pages": ["examples/full_stack", "examples/api_server", "examples/discord_bot", "examples/slack_bot", "examples/telegram_bot", "examples/whatsapp_bot", "examples/poe_bot"]
|
||||
"group": "REST API",
|
||||
"pages": [
|
||||
"rest-api/getting-started",
|
||||
"rest-api/create",
|
||||
"rest-api/get-all-apps",
|
||||
"rest-api/add-data",
|
||||
"rest-api/get-data",
|
||||
"rest-api/query",
|
||||
"rest-api/deploy",
|
||||
"rest-api/delete",
|
||||
"rest-api/check-status"
|
||||
]
|
||||
},
|
||||
{
|
||||
"group": "Use Cases",
|
||||
"pages": [
|
||||
"examples/full_stack",
|
||||
"examples/discord_bot",
|
||||
"examples/slack_bot",
|
||||
"examples/telegram_bot",
|
||||
"examples/whatsapp_bot",
|
||||
"examples/poe_bot"
|
||||
]
|
||||
},
|
||||
{
|
||||
"group": "Community",
|
||||
"pages": [
|
||||
"community/connect-with-us",
|
||||
"community/showcase"
|
||||
]
|
||||
"pages": ["community/connect-with-us", "community/showcase"]
|
||||
},
|
||||
{
|
||||
"group": "Integrations",
|
||||
@@ -92,22 +145,33 @@
|
||||
},
|
||||
{
|
||||
"group": "Product",
|
||||
"pages": [
|
||||
"product/release-notes"
|
||||
]
|
||||
"pages": ["product/release-notes"]
|
||||
}
|
||||
|
||||
],
|
||||
|
||||
"footerSocials": {
|
||||
"website": "https://embedchain.ai",
|
||||
"github": "https://github.com/embedchain/embedchain",
|
||||
"slack":"https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw",
|
||||
"slack": "https://join.slack.com/t/embedchain/shared_invite/zt-22uwz3c46-Zg7cIh5rOBteT_xe1jwLDw",
|
||||
"discord": "https://discord.gg/6PzXDgEjG5",
|
||||
"twitter": "https://twitter.com/embedchain",
|
||||
"linkedin": "https://www.linkedin.com/company/embedchain"
|
||||
},
|
||||
"backgroundImage": "/background.png",
|
||||
"isWhiteLabeled": true,
|
||||
"feedback.thumbsRating": true
|
||||
"analytics": {
|
||||
"posthog": {
|
||||
"apiKey": "phc_PHQDA5KwztijnSojsxJ2c1DuJd52QCzJzT2xnSGvjN2",
|
||||
"apiHost": "https://app.embedchain.ai/ingest"
|
||||
}
|
||||
},
|
||||
"feedback": {
|
||||
"suggestEdit": true,
|
||||
"raiseIssue": true,
|
||||
"thumbsRating": true
|
||||
},
|
||||
"search": {
|
||||
"prompt": "✨ Search embedchain docs..."
|
||||
},
|
||||
"api": {
|
||||
"baseUrl": "http://localhost:8080"
|
||||
}
|
||||
}
|
||||
|
||||
@@ -0,0 +1,427 @@
|
||||
{
|
||||
"openapi": "3.1.0",
|
||||
"info": {
|
||||
"title": "Embedchain REST API",
|
||||
"description": "This is the REST API for Embedchain.",
|
||||
"license": {
|
||||
"name": "Apache 2.0",
|
||||
"url": "https://github.com/embedchain/embedchain/blob/main/LICENSE"
|
||||
},
|
||||
"version": "0.0.1"
|
||||
},
|
||||
"paths": {
|
||||
"/ping": {
|
||||
"get": {
|
||||
"tags": ["Utility"],
|
||||
"summary": "Check status",
|
||||
"description": "Endpoint to check the status of the API",
|
||||
"operationId": "check_status_ping_get",
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": { "application/json": { "schema": {} } }
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/apps": {
|
||||
"get": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Get all apps",
|
||||
"description": "Get all applications",
|
||||
"operationId": "get_all_apps_apps_get",
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": { "application/json": { "schema": {} } }
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/create": {
|
||||
"post": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Create app",
|
||||
"description": "Create a new app using App ID",
|
||||
"operationId": "create_app_using_default_config_create_post",
|
||||
"parameters": [
|
||||
{
|
||||
"name": "app_id",
|
||||
"in": "query",
|
||||
"required": true,
|
||||
"schema": { "type": "string", "title": "App Id" }
|
||||
}
|
||||
],
|
||||
"requestBody": {
|
||||
"content": {
|
||||
"multipart/form-data": {
|
||||
"schema": {
|
||||
"allOf": [
|
||||
{
|
||||
"$ref": "#/components/schemas/Body_create_app_using_default_config_create_post"
|
||||
}
|
||||
],
|
||||
"title": "Body"
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/DefaultResponse" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"422": {
|
||||
"description": "Validation Error",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/HTTPValidationError" }
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/{app_id}/data": {
|
||||
"get": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Get data",
|
||||
"description": "Get all data sources for an app",
|
||||
"operationId": "get_datasources_associated_with_app_id__app_id__data_get",
|
||||
"parameters": [
|
||||
{
|
||||
"name": "app_id",
|
||||
"in": "path",
|
||||
"required": true,
|
||||
"schema": { "type": "string", "title": "App Id" }
|
||||
}
|
||||
],
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": { "application/json": { "schema": {} } }
|
||||
},
|
||||
"422": {
|
||||
"description": "Validation Error",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/HTTPValidationError" }
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/{app_id}/add": {
|
||||
"post": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Add data",
|
||||
"description": "Add a data source to an app.",
|
||||
"operationId": "add_datasource_to_an_app__app_id__add_post",
|
||||
"parameters": [
|
||||
{
|
||||
"name": "app_id",
|
||||
"in": "path",
|
||||
"required": true,
|
||||
"schema": { "type": "string", "title": "App Id" }
|
||||
}
|
||||
],
|
||||
"requestBody": {
|
||||
"required": true,
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/SourceApp" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/DefaultResponse" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"422": {
|
||||
"description": "Validation Error",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/HTTPValidationError" }
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/{app_id}/query": {
|
||||
"post": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Query app",
|
||||
"description": "Query an app",
|
||||
"operationId": "query_an_app__app_id__query_post",
|
||||
"parameters": [
|
||||
{
|
||||
"name": "app_id",
|
||||
"in": "path",
|
||||
"required": true,
|
||||
"schema": { "type": "string", "title": "App Id" }
|
||||
}
|
||||
],
|
||||
"requestBody": {
|
||||
"required": true,
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/QueryApp" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/DefaultResponse" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"422": {
|
||||
"description": "Validation Error",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/HTTPValidationError" }
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/{app_id}/chat": {
|
||||
"post": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Chat",
|
||||
"description": "Chat with an app.\n\napp_id: The ID of the app. Use \"default\" for the default app.\n\nmessage: The message that you want to send to the app.",
|
||||
"operationId": "chat_with_an_app__app_id__chat_post",
|
||||
"parameters": [
|
||||
{
|
||||
"name": "app_id",
|
||||
"in": "path",
|
||||
"required": true,
|
||||
"schema": { "type": "string", "title": "App Id" }
|
||||
}
|
||||
],
|
||||
"requestBody": {
|
||||
"required": true,
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/MessageApp" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/DefaultResponse" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"422": {
|
||||
"description": "Validation Error",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/HTTPValidationError" }
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/{app_id}/deploy": {
|
||||
"post": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Deploy App",
|
||||
"description": "Deploy an existing app.",
|
||||
"operationId": "deploy_app__app_id__deploy_post",
|
||||
"parameters": [
|
||||
{
|
||||
"name": "app_id",
|
||||
"in": "path",
|
||||
"required": true,
|
||||
"schema": { "type": "string", "title": "App Id" }
|
||||
}
|
||||
],
|
||||
"requestBody": {
|
||||
"required": true,
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/DeployAppRequest" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/DefaultResponse" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"422": {
|
||||
"description": "Validation Error",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/HTTPValidationError" }
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"/{app_id}/delete": {
|
||||
"delete": {
|
||||
"tags": ["Apps"],
|
||||
"summary": "Delete app",
|
||||
"description": "Delete an existing app",
|
||||
"operationId": "delete_app__app_id__delete_delete",
|
||||
"parameters": [
|
||||
{
|
||||
"name": "app_id",
|
||||
"in": "path",
|
||||
"required": true,
|
||||
"schema": { "type": "string", "title": "App Id" }
|
||||
}
|
||||
],
|
||||
"responses": {
|
||||
"200": {
|
||||
"description": "Successful Response",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/DefaultResponse" }
|
||||
}
|
||||
}
|
||||
},
|
||||
"422": {
|
||||
"description": "Validation Error",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"schema": { "$ref": "#/components/schemas/HTTPValidationError" }
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
"components": {
|
||||
"schemas": {
|
||||
"Body_create_app_using_default_config_create_post": {
|
||||
"properties": {
|
||||
"config": { "type": "string", "format": "binary", "title": "Config" }
|
||||
},
|
||||
"type": "object",
|
||||
"title": "Body_create_app_using_default_config_create_post"
|
||||
},
|
||||
"DefaultResponse": {
|
||||
"properties": { "response": { "type": "string", "title": "Response" } },
|
||||
"type": "object",
|
||||
"required": ["response"],
|
||||
"title": "DefaultResponse"
|
||||
},
|
||||
"DeployAppRequest": {
|
||||
"properties": {
|
||||
"api_key": {
|
||||
"type": "string",
|
||||
"title": "Api Key",
|
||||
"description": "The Embedchain API key for app deployments. You get the api key on the Embedchain platform by visiting [https://app.embedchain.ai](https://app.embedchain.ai)",
|
||||
"default": ""
|
||||
}
|
||||
},
|
||||
"type": "object",
|
||||
"title": "DeployAppRequest",
|
||||
"example":{
|
||||
"api_key":"ec-xxx"
|
||||
}
|
||||
},
|
||||
"HTTPValidationError": {
|
||||
"properties": {
|
||||
"detail": {
|
||||
"items": { "$ref": "#/components/schemas/ValidationError" },
|
||||
"type": "array",
|
||||
"title": "Detail"
|
||||
}
|
||||
},
|
||||
"type": "object",
|
||||
"title": "HTTPValidationError"
|
||||
},
|
||||
"MessageApp": {
|
||||
"properties": {
|
||||
"message": {
|
||||
"type": "string",
|
||||
"title": "Message",
|
||||
"description": "The message that you want to send to the App.",
|
||||
"default": ""
|
||||
}
|
||||
},
|
||||
"type": "object",
|
||||
"title": "MessageApp"
|
||||
},
|
||||
"QueryApp": {
|
||||
"properties": {
|
||||
"query": {
|
||||
"type": "string",
|
||||
"title": "Query",
|
||||
"description": "The query that you want to ask the App.",
|
||||
"default": ""
|
||||
}
|
||||
},
|
||||
"type": "object",
|
||||
"title": "QueryApp",
|
||||
"example":{
|
||||
"query":"Who is Elon Musk?"
|
||||
}
|
||||
},
|
||||
"SourceApp": {
|
||||
"properties": {
|
||||
"source": {
|
||||
"type": "string",
|
||||
"title": "Source",
|
||||
"description": "The source that you want to add to the App.",
|
||||
"default": ""
|
||||
},
|
||||
"data_type": {
|
||||
"anyOf": [{ "type": "string" }, { "type": "null" }],
|
||||
"title": "Data Type",
|
||||
"description": "The type of data to add, remove it if you want Embedchain to detect it automatically.",
|
||||
"default": ""
|
||||
}
|
||||
},
|
||||
"type": "object",
|
||||
"title": "SourceApp",
|
||||
"example":{
|
||||
"source":"https://en.wikipedia.org/wiki/Elon_Musk"
|
||||
}
|
||||
},
|
||||
"ValidationError": {
|
||||
"properties": {
|
||||
"loc": {
|
||||
"items": { "anyOf": [{ "type": "string" }, { "type": "integer" }] },
|
||||
"type": "array",
|
||||
"title": "Location"
|
||||
},
|
||||
"msg": { "type": "string", "title": "Message" },
|
||||
"type": { "type": "string", "title": "Error Type" }
|
||||
},
|
||||
"type": "object",
|
||||
"required": ["loc", "msg", "type"],
|
||||
"title": "ValidationError"
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,22 @@
|
||||
---
|
||||
openapi: post /{app_id}/add
|
||||
---
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/{app_id}/add \
|
||||
-d "source=https://www.forbes.com/profile/elon-musk" \
|
||||
-d "data_type=web_page"
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{ "response": "fec7fe91e6b2d732938a2ec2e32bfe3f" }
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
@@ -0,0 +1,3 @@
|
||||
---
|
||||
openapi: post /{app_id}/chat
|
||||
---
|
||||
@@ -0,0 +1,20 @@
|
||||
---
|
||||
openapi: get /ping
|
||||
---
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request GET \
|
||||
--url http://localhost:8080/ping
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{ "ping": "pong" }
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
@@ -0,0 +1,95 @@
|
||||
---
|
||||
openapi: post /create
|
||||
---
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/create?app_id=app1 \
|
||||
-F "config=@/path/to/config.yaml"
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{ "response": "App created successfully. App ID: app1" }
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
|
||||
By default we will use the opensource **gpt4all** model to get started. You can also specify your own config by uploading a config YAML file.
|
||||
|
||||
For example, create a `config.yaml` file (adjust according to your requirements):
|
||||
|
||||
```yaml
|
||||
app:
|
||||
config:
|
||||
id: "default-app"
|
||||
|
||||
llm:
|
||||
provider: openai
|
||||
config:
|
||||
model: "gpt-3.5-turbo"
|
||||
temperature: 0.5
|
||||
max_tokens: 1000
|
||||
top_p: 1
|
||||
stream: false
|
||||
template: |
|
||||
Use the following pieces of context to answer the query at the end.
|
||||
If you don't know the answer, just say that you don't know, don't try to make up an answer.
|
||||
|
||||
$context
|
||||
|
||||
Query: $query
|
||||
|
||||
Helpful Answer:
|
||||
|
||||
vectordb:
|
||||
provider: chroma
|
||||
config:
|
||||
collection_name: "rest-api-app"
|
||||
dir: db
|
||||
allow_reset: true
|
||||
|
||||
embedder:
|
||||
provider: openai
|
||||
config:
|
||||
model: "text-embedding-ada-002"
|
||||
```
|
||||
|
||||
To learn more about custom configurations, check out the [custom configurations docs](https://docs.embedchain.ai/advanced/configuration). To explore more examples of config yamls for embedchain, visit [embedchain/configs](https://github.com/embedchain/embedchain/tree/main/configs).
|
||||
|
||||
Now, you can upload this config file in the request body.
|
||||
|
||||
For example,
|
||||
|
||||
```bash Request
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/create?app_id=my-app \
|
||||
-F "config=@/path/to/config.yaml"
|
||||
```
|
||||
|
||||
**Note:** To use custom models, an **API key** might be required. Refer to the table below to determine the necessary API key for your provider.
|
||||
|
||||
| Keys | Providers |
|
||||
| -------------------------- | ------------------------------ |
|
||||
| `OPENAI_API_KEY ` | OpenAI, Azure OpenAI, Jina etc |
|
||||
| `OPENAI_API_TYPE` | Azure OpenAI |
|
||||
| `OPENAI_API_BASE` | Azure OpenAI |
|
||||
| `OPENAI_API_VERSION` | Azure OpenAI |
|
||||
| `COHERE_API_KEY` | Cohere |
|
||||
| `ANTHROPIC_API_KEY` | Anthropic |
|
||||
| `JINACHAT_API_KEY` | Jina |
|
||||
| `HUGGINGFACE_ACCESS_TOKEN` | Huggingface |
|
||||
| `REPLICATE_API_TOKEN` | LLAMA2 |
|
||||
|
||||
To add env variables, you can simply run the docker command with the `-e` flag.
|
||||
|
||||
For example,
|
||||
|
||||
```bash
|
||||
docker run --name embedchain -p 8080:8080 -e OPENAI_API_KEY=<YOUR_OPENAI_API_KEY> embedchain/rest-api:latest
|
||||
```
|
||||
@@ -0,0 +1,21 @@
|
||||
---
|
||||
openapi: delete /{app_id}/delete
|
||||
---
|
||||
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request DELETE \
|
||||
--url http://localhost:8080/{app_id}/delete
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{ "response": "App with id {app_id} deleted successfully." }
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
@@ -0,0 +1,22 @@
|
||||
---
|
||||
openapi: post /{app_id}/deploy
|
||||
---
|
||||
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/{app_id}/deploy \
|
||||
-d "api_key=ec-xxxx"
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{ "response": "App deployed successfully." }
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
@@ -0,0 +1,33 @@
|
||||
---
|
||||
openapi: get /apps
|
||||
---
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request GET \
|
||||
--url http://localhost:8080/apps
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{
|
||||
"results": [
|
||||
{
|
||||
"config": "config1.yaml",
|
||||
"id": 1,
|
||||
"app_id": "app1"
|
||||
},
|
||||
{
|
||||
"config": "config2.yaml",
|
||||
"id": 2,
|
||||
"app_id": "app2"
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
@@ -0,0 +1,28 @@
|
||||
---
|
||||
openapi: get /{app_id}/data
|
||||
---
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request GET \
|
||||
--url http://localhost:8080/{app_id}/data
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{
|
||||
"results": [
|
||||
{
|
||||
"data_type": "web_page",
|
||||
"data_value": "https://www.forbes.com/profile/elon-musk/",
|
||||
"metadata": "null"
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
@@ -0,0 +1,294 @@
|
||||
---
|
||||
title: "🌍 Getting Started"
|
||||
---
|
||||
|
||||
## Quickstart
|
||||
|
||||
To use Embedchain as a REST API service, run the following command:
|
||||
|
||||
```bash
|
||||
docker run --name embedchain -p 8080:8080 embedchain/rest-api:latest
|
||||
```
|
||||
|
||||
Navigate to [http://localhost:8080/docs](http://localhost:8080/docs) to interact with the API. There is a full-fledged Swagger docs playground with all the information about the API endpoints.
|
||||
|
||||
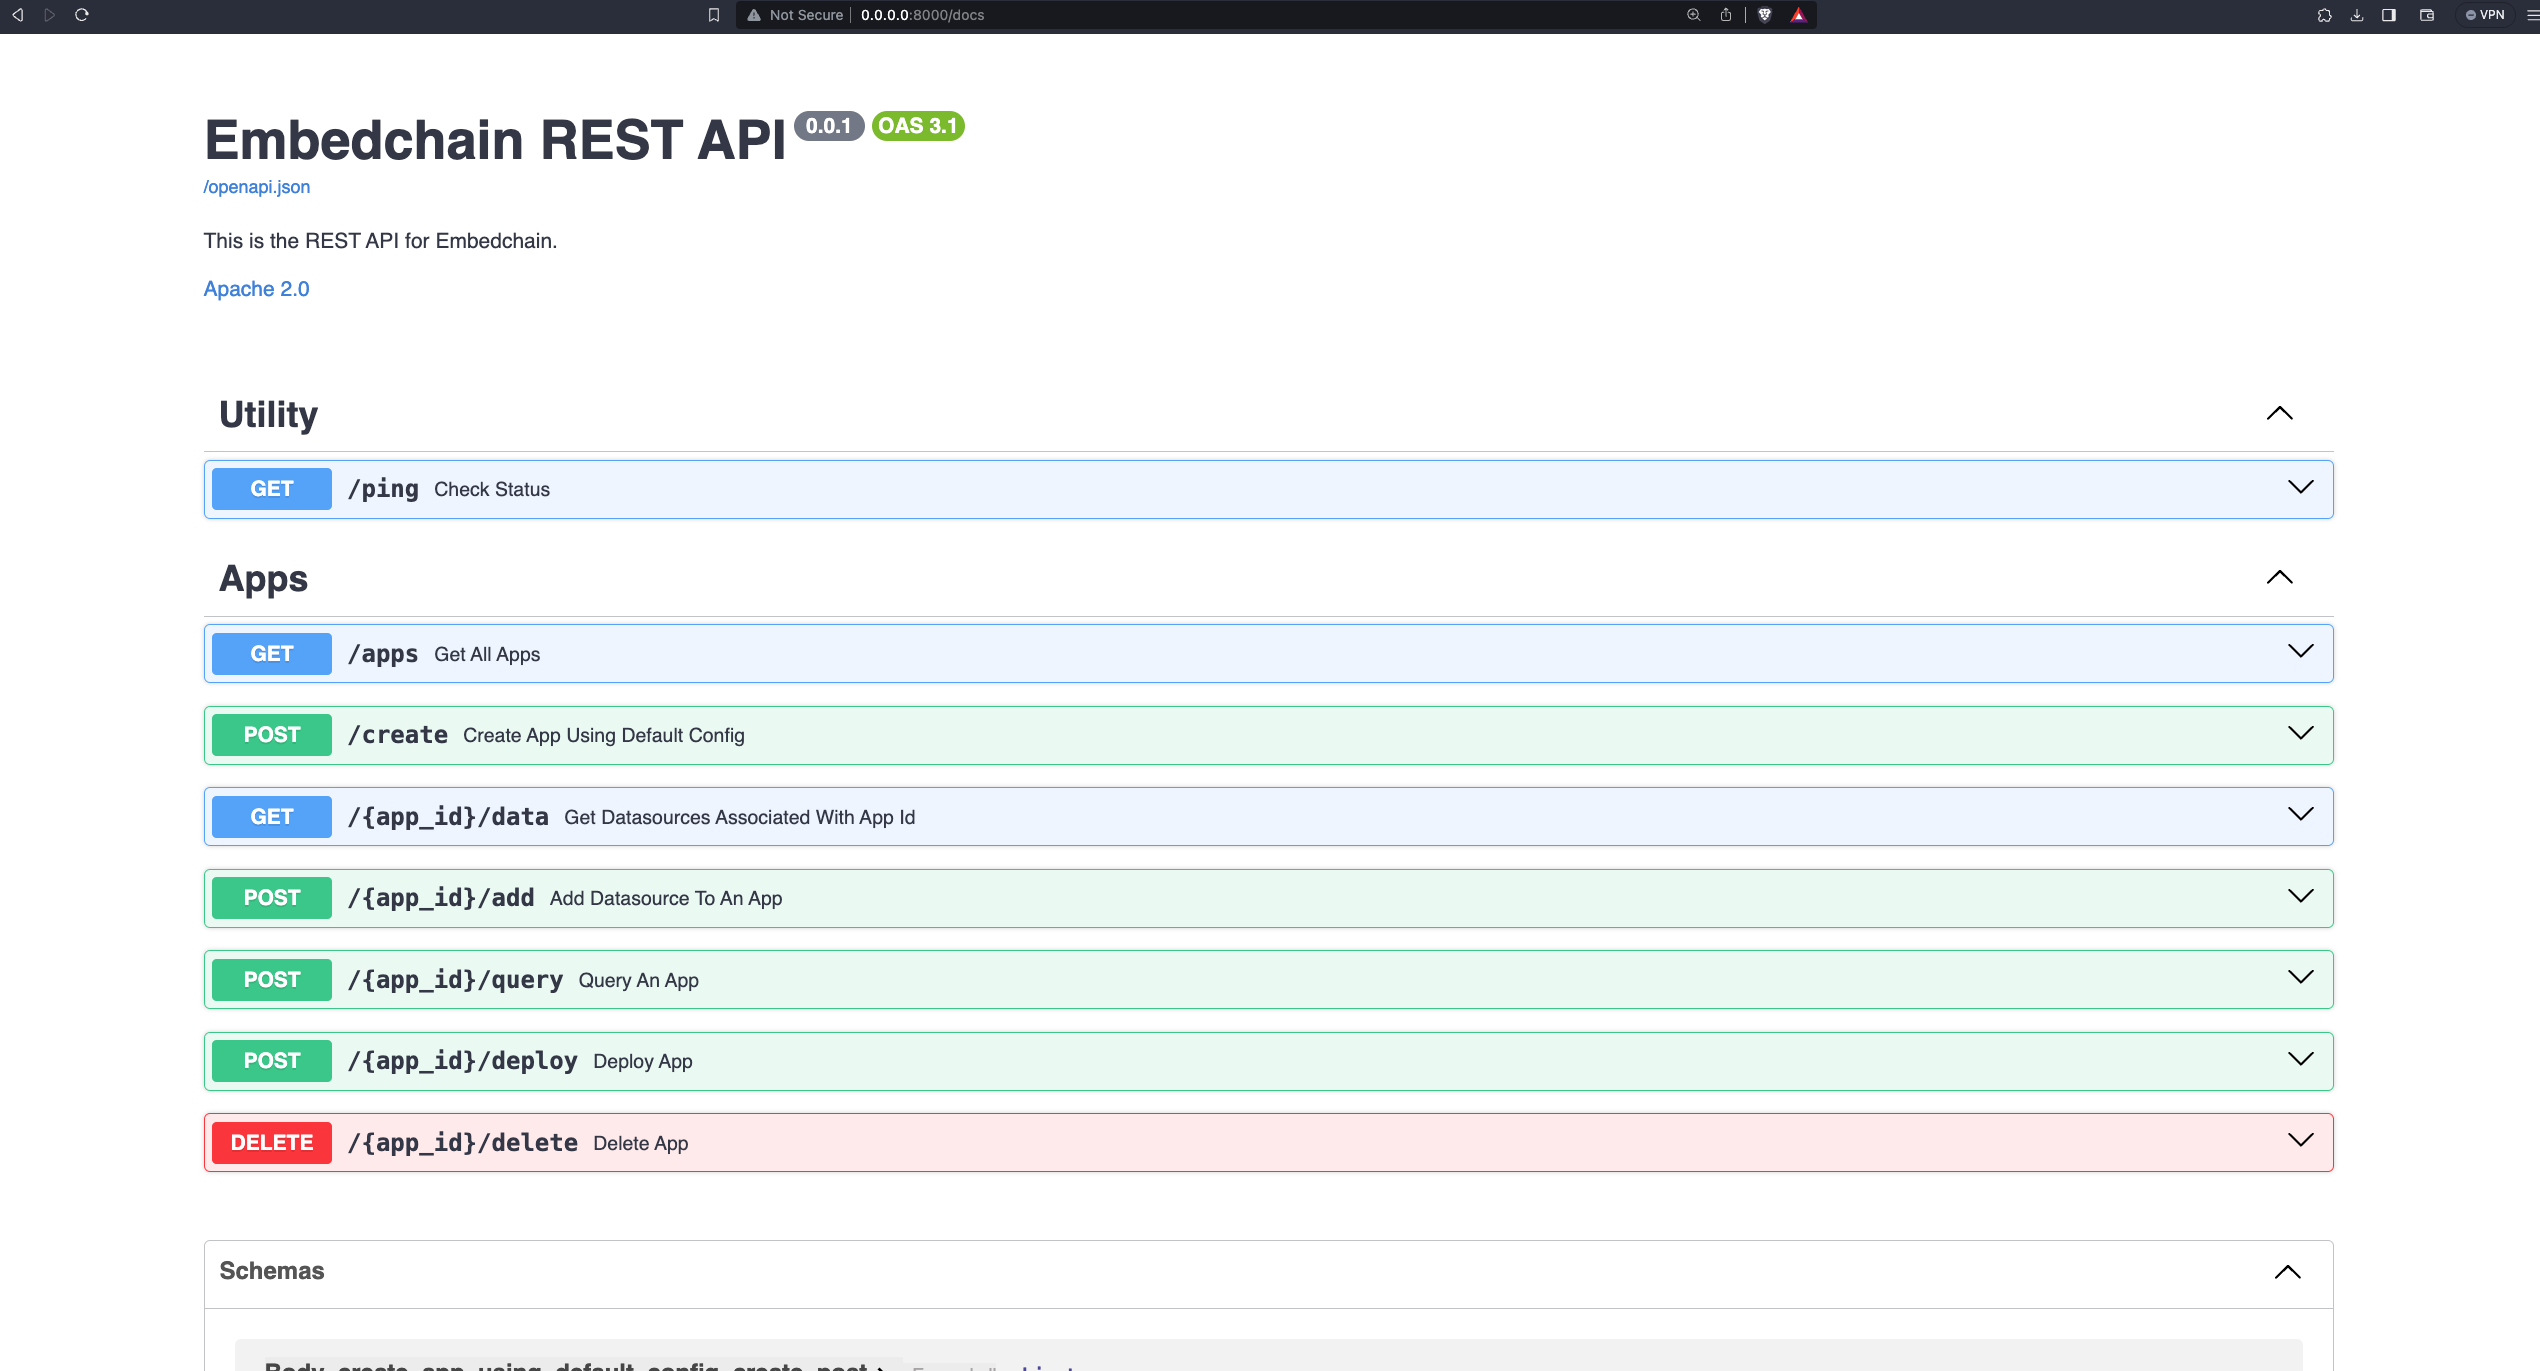
|
||||
|
||||
## ⚡ Steps to get started
|
||||
|
||||
<Steps>
|
||||
<Step title="⚙️ Create an app">
|
||||
<Tabs>
|
||||
<Tab title="cURL">
|
||||
```bash
|
||||
curl --request POST "http://localhost:8080/create?app_id=my-app" \
|
||||
-H "accept: application/json"
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="python">
|
||||
```python
|
||||
import requests
|
||||
|
||||
url = "http://localhost:8080/create?app_id=my-app"
|
||||
|
||||
payload={}
|
||||
|
||||
response = requests.request("POST", url, data=payload)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="javascript">
|
||||
```javascript
|
||||
const data = fetch("http://localhost:8080/create?app_id=my-app", {
|
||||
method: "POST",
|
||||
}).then((res) => res.json());
|
||||
|
||||
console.log(data);
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="go">
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"net/http"
|
||||
"io/ioutil"
|
||||
)
|
||||
|
||||
func main() {
|
||||
|
||||
url := "http://localhost:8080/create?app_id=my-app"
|
||||
|
||||
payload := strings.NewReader("")
|
||||
|
||||
req, _ := http.NewRequest("POST", url, payload)
|
||||
|
||||
req.Header.Add("Content-Type", "application/json")
|
||||
|
||||
res, _ := http.DefaultClient.Do(req)
|
||||
|
||||
defer res.Body.Close()
|
||||
body, _ := ioutil.ReadAll(res.Body)
|
||||
|
||||
fmt.Println(res)
|
||||
fmt.Println(string(body))
|
||||
|
||||
}
|
||||
```
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
</Step>
|
||||
<Step title="🗃️ Add data sources">
|
||||
<Tabs>
|
||||
<Tab title="cURL">
|
||||
```bash
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/my-app/add \
|
||||
-d "source=https://www.forbes.com/profile/elon-musk" \
|
||||
-d "data_type=web_page"
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="python">
|
||||
```python
|
||||
import requests
|
||||
|
||||
url = "http://localhost:8080/my-app/add"
|
||||
|
||||
payload = "source=https://www.forbes.com/profile/elon-musk&data_type=web_page"
|
||||
headers = {}
|
||||
|
||||
response = requests.request("POST", url, headers=headers, data=payload)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="javascript">
|
||||
```javascript
|
||||
const data = fetch("http://localhost:8080/my-app/add", {
|
||||
method: "POST",
|
||||
body: "source=https://www.forbes.com/profile/elon-musk&data_type=web_page",
|
||||
}).then((res) => res.json());
|
||||
|
||||
console.log(data);
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="go">
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"strings"
|
||||
"net/http"
|
||||
"io/ioutil"
|
||||
)
|
||||
|
||||
func main() {
|
||||
|
||||
url := "http://localhost:8080/my-app/add"
|
||||
|
||||
payload := strings.NewReader("source=https://www.forbes.com/profile/elon-musk&data_type=web_page")
|
||||
|
||||
req, _ := http.NewRequest("POST", url, payload)
|
||||
|
||||
req.Header.Add("Content-Type", "application/x-www-form-urlencoded")
|
||||
|
||||
res, _ := http.DefaultClient.Do(req)
|
||||
|
||||
defer res.Body.Close()
|
||||
body, _ := ioutil.ReadAll(res.Body)
|
||||
|
||||
fmt.Println(res)
|
||||
fmt.Println(string(body))
|
||||
|
||||
}
|
||||
```
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
</Step>
|
||||
<Step title="💬 Query on your data">
|
||||
<Tabs>
|
||||
<Tab title="cURL">
|
||||
```bash
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/my-app/query \
|
||||
-d "query=Who is Elon Musk?"
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="python">
|
||||
```python
|
||||
import requests
|
||||
|
||||
url = "http://localhost:8080/my-app/query"
|
||||
|
||||
payload = "query=Who is Elon Musk?"
|
||||
headers = {}
|
||||
|
||||
response = requests.request("POST", url, headers=headers, data=payload)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="javascript">
|
||||
```javascript
|
||||
const data = fetch("http://localhost:8080/my-app/query", {
|
||||
method: "POST",
|
||||
body: "query=Who is Elon Musk?",
|
||||
}).then((res) => res.json());
|
||||
|
||||
console.log(data);
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="go">
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"strings"
|
||||
"net/http"
|
||||
"io/ioutil"
|
||||
)
|
||||
|
||||
func main() {
|
||||
|
||||
url := "http://localhost:8080/my-app/query"
|
||||
|
||||
payload := strings.NewReader("query=Who is Elon Musk?")
|
||||
|
||||
req, _ := http.NewRequest("POST", url, payload)
|
||||
|
||||
req.Header.Add("Content-Type", "application/x-www-form-urlencoded")
|
||||
|
||||
res, _ := http.DefaultClient.Do(req)
|
||||
|
||||
defer res.Body.Close()
|
||||
body, _ := ioutil.ReadAll(res.Body)
|
||||
|
||||
fmt.Println(res)
|
||||
fmt.Println(string(body))
|
||||
|
||||
}
|
||||
```
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
</Step>
|
||||
<Step title="🚀 (Optional) Deploy your app to Embedchain Platform">
|
||||
<Tabs>
|
||||
<Tab title="cURL">
|
||||
```bash
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/my-app/deploy \
|
||||
-d "api_key=ec-xxxx"
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="python">
|
||||
```python
|
||||
import requests
|
||||
|
||||
url = "http://localhost:8080/my-app/deploy"
|
||||
|
||||
payload = "api_key=ec-xxxx"
|
||||
|
||||
response = requests.request("POST", url, data=payload)
|
||||
|
||||
print(response)
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="javascript">
|
||||
```javascript
|
||||
const data = fetch("http://localhost:8080/my-app/deploy", {
|
||||
method: "POST",
|
||||
body: "api_key=ec-xxxx",
|
||||
}).then((res) => res.json());
|
||||
|
||||
console.log(data);
|
||||
```
|
||||
</Tab>
|
||||
<Tab title="go">
|
||||
```go
|
||||
package main
|
||||
|
||||
import (
|
||||
"fmt"
|
||||
"strings"
|
||||
"net/http"
|
||||
"io/ioutil"
|
||||
)
|
||||
|
||||
func main() {
|
||||
|
||||
url := "http://localhost:8080/my-app/deploy"
|
||||
|
||||
payload := strings.NewReader("api_key=ec-xxxx")
|
||||
|
||||
req, _ := http.NewRequest("POST", url, payload)
|
||||
|
||||
req.Header.Add("Content-Type", "application/x-www-form-urlencoded")
|
||||
|
||||
res, _ := http.DefaultClient.Do(req)
|
||||
|
||||
defer res.Body.Close()
|
||||
body, _ := ioutil.ReadAll(res.Body)
|
||||
|
||||
fmt.Println(res)
|
||||
fmt.Println(string(body))
|
||||
|
||||
}
|
||||
```
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
</Step>
|
||||
</Steps>
|
||||
|
||||
And you're ready! 🎉
|
||||
|
||||
If you run into issues, please feel free to contact us using below links:
|
||||
|
||||
<Snippet file="get-help.mdx" />
|
||||
@@ -0,0 +1,21 @@
|
||||
---
|
||||
openapi: post /{app_id}/query
|
||||
---
|
||||
|
||||
<RequestExample>
|
||||
|
||||
```bash Request
|
||||
curl --request POST \
|
||||
--url http://localhost:8080/{app_id}/query \
|
||||
-d "query=who is Elon Musk?"
|
||||
```
|
||||
|
||||
</RequestExample>
|
||||
|
||||
<ResponseExample>
|
||||
|
||||
```json Response
|
||||
{ "response": "Net worth of Elon Musk is $218 Billion." }
|
||||
```
|
||||
|
||||
</ResponseExample>
|
||||
@@ -3,9 +3,9 @@ import importlib.metadata
|
||||
__version__ = importlib.metadata.version(__package__ or __name__)
|
||||
|
||||
from embedchain.apps.app import App # noqa: F401
|
||||
from embedchain.apps.custom_app import CustomApp # noqa: F401
|
||||
from embedchain.apps.Llama2App import Llama2App # noqa: F401
|
||||
from embedchain.apps.open_source_app import OpenSourceApp # noqa: F401
|
||||
from embedchain.apps.person_app import (PersonApp, # noqa: F401
|
||||
PersonOpenSourceApp)
|
||||
from embedchain.client import Client # noqa: F401
|
||||
from embedchain.pipeline import Pipeline # noqa: F401
|
||||
from embedchain.vectordb.chroma import ChromaDB # noqa: F401
|
||||
|
||||
# Setup the user directory if doesn't exist already
|
||||
Client.setup_dir()
|
||||
|
||||
@@ -1,38 +0,0 @@
|
||||
import logging
|
||||
from typing import Optional
|
||||
|
||||
from embedchain.apps.app import App
|
||||
from embedchain.config import CustomAppConfig
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.llm.llama2 import Llama2Llm
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class Llama2App(App):
|
||||
"""
|
||||
The EmbedChain Llama2App class.
|
||||
|
||||
Methods:
|
||||
add(source, data_type): adds the data from the given URL to the vector db.
|
||||
query(query): finds answer to the given query using vector database and LLM.
|
||||
chat(query): finds answer to the given query using vector database and LLM, with conversation history.
|
||||
|
||||
.. deprecated:: 0.0.64
|
||||
Use `App` instead.
|
||||
"""
|
||||
|
||||
def __init__(self, config: CustomAppConfig = None, system_prompt: Optional[str] = None):
|
||||
"""
|
||||
.. deprecated:: 0.0.64
|
||||
Use `App` instead.
|
||||
|
||||
:param config: CustomAppConfig instance to load as configuration. Optional.
|
||||
:param system_prompt: System prompt string. Optional.
|
||||
"""
|
||||
logging.warning(
|
||||
"DEPRECATION WARNING: Please use `App` instead of `Llama2App`. "
|
||||
"`Llama2App` will be removed in a future release. "
|
||||
"Please refer to https://docs.embedchain.ai/advanced/app_types#llama2app for instructions."
|
||||
)
|
||||
|
||||
super().__init__(config=config, llm=Llama2Llm(), system_prompt=system_prompt)
|
||||
@@ -2,15 +2,17 @@ from typing import Optional
|
||||
|
||||
import yaml
|
||||
|
||||
from embedchain.config import AppConfig, BaseEmbedderConfig, BaseLlmConfig
|
||||
from embedchain.config import (AppConfig, BaseEmbedderConfig, BaseLlmConfig,
|
||||
ChunkerConfig)
|
||||
from embedchain.config.vectordb.base import BaseVectorDbConfig
|
||||
from embedchain.embedchain import EmbedChain
|
||||
from embedchain.embedder.base import BaseEmbedder
|
||||
from embedchain.embedder.openai import OpenAIEmbedder
|
||||
from embedchain.factory import EmbedderFactory, LlmFactory, VectorDBFactory
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
from embedchain.llm.base import BaseLlm
|
||||
from embedchain.llm.openai import OpenAILlm
|
||||
from embedchain.utils import validate_config
|
||||
from embedchain.vectordb.base import BaseVectorDB
|
||||
from embedchain.vectordb.chroma import ChromaDB
|
||||
|
||||
@@ -37,6 +39,7 @@ class App(EmbedChain):
|
||||
embedder: BaseEmbedder = None,
|
||||
embedder_config: Optional[BaseEmbedderConfig] = None,
|
||||
system_prompt: Optional[str] = None,
|
||||
chunker: Optional[ChunkerConfig] = None,
|
||||
):
|
||||
"""
|
||||
Initialize a new `App` instance.
|
||||
@@ -96,6 +99,9 @@ class App(EmbedChain):
|
||||
if embedder is None:
|
||||
embedder = OpenAIEmbedder(config=embedder_config)
|
||||
|
||||
self.chunker = None
|
||||
if chunker:
|
||||
self.chunker = ChunkerConfig(**chunker)
|
||||
# Type check assignments
|
||||
if not isinstance(llm, BaseLlm):
|
||||
raise TypeError(
|
||||
@@ -127,10 +133,16 @@ class App(EmbedChain):
|
||||
with open(yaml_path, "r") as file:
|
||||
config_data = yaml.safe_load(file)
|
||||
|
||||
try:
|
||||
validate_config(config_data)
|
||||
except Exception as e:
|
||||
raise Exception(f"❌ Error occurred while validating the YAML config. Error: {str(e)}")
|
||||
|
||||
app_config_data = config_data.get("app", {})
|
||||
llm_config_data = config_data.get("llm", {})
|
||||
db_config_data = config_data.get("vectordb", {})
|
||||
embedder_config_data = config_data.get("embedder", {})
|
||||
embedding_model_config_data = config_data.get("embedding_model", config_data.get("embedder", {}))
|
||||
chunker_config_data = config_data.get("chunker", {})
|
||||
|
||||
app_config = AppConfig(**app_config_data.get("config", {}))
|
||||
|
||||
@@ -140,6 +152,6 @@ class App(EmbedChain):
|
||||
db_provider = db_config_data.get("provider", "chroma")
|
||||
db = VectorDBFactory.create(db_provider, db_config_data.get("config", {}))
|
||||
|
||||
embedder_provider = embedder_config_data.get("provider", "openai")
|
||||
embedder = EmbedderFactory.create(embedder_provider, embedder_config_data.get("config", {}))
|
||||
return cls(config=app_config, llm=llm, db=db, embedder=embedder)
|
||||
embedder_provider = embedding_model_config_data.get("provider", "openai")
|
||||
embedder = EmbedderFactory.create(embedder_provider, embedding_model_config_data.get("config", {}))
|
||||
return cls(config=app_config, llm=llm, db=db, embedder=embedder, chunker=chunker_config_data)
|
||||
|
||||
@@ -1,63 +0,0 @@
|
||||
import logging
|
||||
from typing import Optional
|
||||
|
||||
from embedchain.apps.app import App
|
||||
from embedchain.config import CustomAppConfig
|
||||
from embedchain.embedder.base import BaseEmbedder
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.llm.base import BaseLlm
|
||||
from embedchain.vectordb.base import BaseVectorDB
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class CustomApp(App):
|
||||
"""
|
||||
Embedchain's custom app allows for most flexibility.
|
||||
|
||||
You can craft your own mix of various LLMs, vector databases and embedding model/functions.
|
||||
|
||||
Methods:
|
||||
add(source, data_type): adds the data from the given URL to the vector db.
|
||||
query(query): finds answer to the given query using vector database and LLM.
|
||||
chat(query): finds answer to the given query using vector database and LLM, with conversation history.
|
||||
|
||||
.. deprecated:: 0.0.64
|
||||
Use `App` instead.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
config: Optional[CustomAppConfig] = None,
|
||||
llm: BaseLlm = None,
|
||||
db: BaseVectorDB = None,
|
||||
embedder: BaseEmbedder = None,
|
||||
system_prompt: Optional[str] = None,
|
||||
):
|
||||
"""
|
||||
Initialize a new `CustomApp` instance. You have to choose a LLM, database and embedder.
|
||||
|
||||
.. deprecated:: 0.0.64
|
||||
Use `App` instead.
|
||||
|
||||
:param config: Config for the app instance. This is the most basic configuration,
|
||||
that does not fall into the LLM, database or embedder category, defaults to None
|
||||
:type config: Optional[CustomAppConfig], optional
|
||||
:param llm: LLM Class instance. example: `from embedchain.llm.openai import OpenAILlm`, defaults to None
|
||||
:type llm: BaseLlm
|
||||
:param db: The database to use for storing and retrieving embeddings,
|
||||
example: `from embedchain.vectordb.chroma_db import ChromaDb`, defaults to None
|
||||
:type db: BaseVectorDB
|
||||
:param embedder: The embedder (embedding model and function) use to calculate embeddings.
|
||||
example: `from embedchain.embedder.gpt4all_embedder import GPT4AllEmbedder`, defaults to None
|
||||
:type embedder: BaseEmbedder
|
||||
:param system_prompt: System prompt that will be provided to the LLM as such, defaults to None
|
||||
:type system_prompt: Optional[str], optional
|
||||
:raises ValueError: LLM, database or embedder has not been defined.
|
||||
:raises TypeError: LLM, database or embedder is not a valid class instance.
|
||||
"""
|
||||
logging.warning(
|
||||
"DEPRECATION WARNING: Please use `App` instead of `CustomApp`. "
|
||||
"`CustomApp` will be removed in a future release. "
|
||||
"Please refer to https://docs.embedchain.ai/advanced/app_types#opensourceapp for instructions."
|
||||
)
|
||||
super().__init__(config=config, llm=llm, db=db, embedder=embedder, system_prompt=system_prompt)
|
||||
@@ -1,71 +0,0 @@
|
||||
import logging
|
||||
from typing import Optional
|
||||
|
||||
from embedchain.apps.app import App
|
||||
from embedchain.config import (BaseLlmConfig, ChromaDbConfig,
|
||||
OpenSourceAppConfig)
|
||||
from embedchain.embedder.gpt4all import GPT4AllEmbedder
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.llm.gpt4all import GPT4ALLLlm
|
||||
from embedchain.vectordb.chroma import ChromaDB
|
||||
|
||||
gpt4all_model = None
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class OpenSourceApp(App):
|
||||
"""
|
||||
The embedchain Open Source App.
|
||||
Comes preconfigured with the best open source LLM, embedding model, database.
|
||||
|
||||
Methods:
|
||||
add(source, data_type): adds the data from the given URL to the vector db.
|
||||
query(query): finds answer to the given query using vector database and LLM.
|
||||
chat(query): finds answer to the given query using vector database and LLM, with conversation history.
|
||||
|
||||
.. deprecated:: 0.0.64
|
||||
Use `App` instead.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
config: OpenSourceAppConfig = None,
|
||||
llm_config: BaseLlmConfig = None,
|
||||
chromadb_config: Optional[ChromaDbConfig] = None,
|
||||
system_prompt: Optional[str] = None,
|
||||
):
|
||||
"""
|
||||
Initialize a new `CustomApp` instance.
|
||||
Since it's opinionated you don't have to choose a LLM, database and embedder.
|
||||
However, you can configure those.
|
||||
|
||||
.. deprecated:: 0.0.64
|
||||
Use `App` instead.
|
||||
|
||||
:param config: Config for the app instance. This is the most basic configuration,
|
||||
that does not fall into the LLM, database or embedder category, defaults to None
|
||||
:type config: OpenSourceAppConfig, optional
|
||||
:param llm_config: Allows you to configure the LLM, e.g. how many documents to return.
|
||||
example: `from embedchain.config import BaseLlmConfig`, defaults to None
|
||||
:type llm_config: BaseLlmConfig, optional
|
||||
:param chromadb_config: Allows you to configure the open source database,
|
||||
example: `from embedchain.config import ChromaDbConfig`, defaults to None
|
||||
:type chromadb_config: Optional[ChromaDbConfig], optional
|
||||
:param system_prompt: System prompt that will be provided to the LLM as such.
|
||||
Please don't use for the time being, as it's not supported., defaults to None
|
||||
:type system_prompt: Optional[str], optional
|
||||
:raises TypeError: `OpenSourceAppConfig` or `BaseLlmConfig` invalid.
|
||||
"""
|
||||
logging.warning(
|
||||
"DEPRECATION WARNING: Please use `App` instead of `OpenSourceApp`."
|
||||
"`OpenSourceApp` will be removed in a future release."
|
||||
"Please refer to https://docs.embedchain.ai/advanced/app_types#customapp for instructions."
|
||||
)
|
||||
|
||||
super().__init__(
|
||||
config=config,
|
||||
llm=GPT4ALLLlm(config=llm_config),
|
||||
db=ChromaDB(config=chromadb_config),
|
||||
embedder=GPT4AllEmbedder(),
|
||||
system_prompt=system_prompt,
|
||||
)
|
||||
@@ -1,93 +0,0 @@
|
||||
from string import Template
|
||||
|
||||
from embedchain.apps.app import App
|
||||
from embedchain.apps.open_source_app import OpenSourceApp
|
||||
from embedchain.config import AppConfig, BaseLlmConfig
|
||||
from embedchain.config.llm.base import (DEFAULT_PROMPT,
|
||||
DEFAULT_PROMPT_WITH_HISTORY)
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class EmbedChainPersonApp:
|
||||
"""
|
||||
Base class to create a person bot.
|
||||
This bot behaves and speaks like a person.
|
||||
|
||||
:param person: name of the person, better if its a well known person.
|
||||
:param config: AppConfig instance to load as configuration.
|
||||
"""
|
||||
|
||||
def __init__(self, person: str, config: AppConfig = None):
|
||||
"""Initialize a new person app
|
||||
|
||||
:param person: Name of the person that's imitated.
|
||||
:type person: str
|
||||
:param config: Configuration class instance, defaults to None
|
||||
:type config: AppConfig, optional
|
||||
"""
|
||||
self.person = person
|
||||
self.person_prompt = f"You are {person}. Whatever you say, you will always say in {person} style." # noqa:E501
|
||||
super().__init__(config)
|
||||
|
||||
def add_person_template_to_config(self, default_prompt: str, config: BaseLlmConfig = None):
|
||||
"""
|
||||
This method checks if the config object contains a prompt template
|
||||
if yes it adds the person prompt to it and return the updated config
|
||||
else it creates a config object with the default prompt added to the person prompt
|
||||
|
||||
:param default_prompt: it is the default prompt for query or chat methods
|
||||
:type default_prompt: str
|
||||
:param config: _description_, defaults to None
|
||||
:type config: BaseLlmConfig, optional
|
||||
:return: The `ChatConfig` instance to use as configuration options.
|
||||
:rtype: _type_
|
||||
"""
|
||||
template = Template(self.person_prompt + " " + default_prompt)
|
||||
|
||||
if config:
|
||||
if config.template:
|
||||
# Add person prompt to custom user template
|
||||
config.template = Template(self.person_prompt + " " + config.template.template)
|
||||
else:
|
||||
# If no user template is present, use person prompt with the default template
|
||||
config.template = template
|
||||
else:
|
||||
# if no config is present at all, initialize the config with person prompt and default template
|
||||
config = BaseLlmConfig(
|
||||
template=template,
|
||||
)
|
||||
|
||||
return config
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class PersonApp(EmbedChainPersonApp, App):
|
||||
"""
|
||||
The Person app.
|
||||
Extends functionality from EmbedChainPersonApp and App
|
||||
"""
|
||||
|
||||
def query(self, input_query, config: BaseLlmConfig = None, dry_run=False):
|
||||
config = self.add_person_template_to_config(DEFAULT_PROMPT, config)
|
||||
return super().query(input_query, config, dry_run, where=None)
|
||||
|
||||
def chat(self, input_query, config: BaseLlmConfig = None, dry_run=False, where=None):
|
||||
config = self.add_person_template_to_config(DEFAULT_PROMPT_WITH_HISTORY, config)
|
||||
return super().chat(input_query, config, dry_run, where)
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class PersonOpenSourceApp(EmbedChainPersonApp, OpenSourceApp):
|
||||
"""
|
||||
The Person app.
|
||||
Extends functionality from EmbedChainPersonApp and OpenSourceApp
|
||||
"""
|
||||
|
||||
def query(self, input_query, config: BaseLlmConfig = None, dry_run=False):
|
||||
config = self.add_person_template_to_config(DEFAULT_PROMPT, config)
|
||||
return super().query(input_query, config, dry_run)
|
||||
|
||||
def chat(self, input_query, config: BaseLlmConfig = None, dry_run=False):
|
||||
config = self.add_person_template_to_config(DEFAULT_PROMPT_WITH_HISTORY, config)
|
||||
return super().chat(input_query, config, dry_run)
|
||||
@@ -1,10 +1,10 @@
|
||||
from typing import Any
|
||||
|
||||
from embedchain import App
|
||||
from embedchain.config import AddConfig, AppConfig, BaseLlmConfig
|
||||
from embedchain import Pipeline as App
|
||||
from embedchain.config import AddConfig, BaseLlmConfig, PipelineConfig
|
||||
from embedchain.embedder.openai import OpenAIEmbedder
|
||||
from embedchain.helper.json_serializable import (JSONSerializable,
|
||||
register_deserializable)
|
||||
from embedchain.helpers.json_serializable import (JSONSerializable,
|
||||
register_deserializable)
|
||||
from embedchain.llm.openai import OpenAILlm
|
||||
from embedchain.vectordb.chroma import ChromaDB
|
||||
|
||||
@@ -12,7 +12,7 @@ from embedchain.vectordb.chroma import ChromaDB
|
||||
@register_deserializable
|
||||
class BaseBot(JSONSerializable):
|
||||
def __init__(self):
|
||||
self.app = App(config=AppConfig(), llm=OpenAILlm(), db=ChromaDB(), embedder=OpenAIEmbedder())
|
||||
self.app = App(config=PipelineConfig(), llm=OpenAILlm(), db=ChromaDB(), embedding_model=OpenAIEmbedder())
|
||||
|
||||
def add(self, data: Any, config: AddConfig = None):
|
||||
"""
|
||||
|
||||
@@ -2,7 +2,7 @@ import argparse
|
||||
import logging
|
||||
import os
|
||||
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
from .base import BaseBot
|
||||
|
||||
|
||||
@@ -3,7 +3,7 @@ import logging
|
||||
import os
|
||||
from typing import List, Optional
|
||||
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
from .base import BaseBot
|
||||
|
||||
|
||||
@@ -5,7 +5,7 @@ import signal
|
||||
import sys
|
||||
|
||||
from embedchain import App
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
from .base import BaseBot
|
||||
|
||||
|
||||
@@ -4,7 +4,7 @@ import logging
|
||||
import signal
|
||||
import sys
|
||||
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
from .base import BaseBot
|
||||
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
import hashlib
|
||||
|
||||
from embedchain.helper.json_serializable import JSONSerializable
|
||||
from embedchain.helpers.json_serializable import JSONSerializable
|
||||
from embedchain.models.data_type import DataType
|
||||
|
||||
|
||||
@@ -44,6 +44,7 @@ class BaseChunker(JSONSerializable):
|
||||
|
||||
for chunk in chunks:
|
||||
chunk_id = hashlib.sha256((chunk + url).encode()).hexdigest()
|
||||
chunk_id = f"{app_id}--{chunk_id}" if app_id is not None else chunk_id
|
||||
if idMap.get(chunk_id) is None:
|
||||
idMap[chunk_id] = True
|
||||
chunk_ids.append(chunk_id)
|
||||
|
||||
@@ -0,0 +1,22 @@
|
||||
from typing import Optional
|
||||
|
||||
from langchain.text_splitter import RecursiveCharacterTextSplitter
|
||||
|
||||
from embedchain.chunkers.base_chunker import BaseChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class CommonChunker(BaseChunker):
|
||||
"""Common chunker for all loaders."""
|
||||
|
||||
def __init__(self, config: Optional[ChunkerConfig] = None):
|
||||
if config is None:
|
||||
config = ChunkerConfig(chunk_size=2000, chunk_overlap=0, length_function=len)
|
||||
text_splitter = RecursiveCharacterTextSplitter(
|
||||
chunk_size=config.chunk_size,
|
||||
chunk_overlap=config.chunk_overlap,
|
||||
length_function=config.length_function,
|
||||
)
|
||||
super().__init__(text_splitter)
|
||||
@@ -0,0 +1,22 @@
|
||||
from typing import Optional
|
||||
|
||||
from langchain.text_splitter import RecursiveCharacterTextSplitter
|
||||
|
||||
from embedchain.chunkers.base_chunker import BaseChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class DiscourseChunker(BaseChunker):
|
||||
"""Chunker for discourse."""
|
||||
|
||||
def __init__(self, config: Optional[ChunkerConfig] = None):
|
||||
if config is None:
|
||||
config = ChunkerConfig(chunk_size=1000, chunk_overlap=0, length_function=len)
|
||||
text_splitter = RecursiveCharacterTextSplitter(
|
||||
chunk_size=config.chunk_size,
|
||||
chunk_overlap=config.chunk_overlap,
|
||||
length_function=config.length_function,
|
||||
)
|
||||
super().__init__(text_splitter)
|
||||
@@ -4,7 +4,7 @@ from langchain.text_splitter import RecursiveCharacterTextSplitter
|
||||
|
||||
from embedchain.chunkers.base_chunker import BaseChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
from embedchain.helper.json_serializable import register_deserializable
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
|
||||
@register_deserializable
|
||||
|
||||
@@ -0,0 +1,22 @@
|
||||
from typing import Optional
|
||||
|
||||
from langchain.text_splitter import RecursiveCharacterTextSplitter
|
||||
|
||||
from embedchain.chunkers.base_chunker import BaseChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class GmailChunker(BaseChunker):
|
||||
"""Chunker for gmail."""
|
||||
|
||||
def __init__(self, config: Optional[ChunkerConfig] = None):
|
||||
if config is None:
|
||||
config = ChunkerConfig(chunk_size=1000, chunk_overlap=0, length_function=len)
|
||||
text_splitter = RecursiveCharacterTextSplitter(
|
||||
chunk_size=config.chunk_size,
|
||||
chunk_overlap=config.chunk_overlap,
|
||||
length_function=config.length_function,
|
||||
)
|
||||
super().__init__(text_splitter)
|
||||
@@ -0,0 +1,22 @@
|
||||
from typing import Optional
|
||||
|
||||
from langchain.text_splitter import RecursiveCharacterTextSplitter
|
||||
|
||||
from embedchain.chunkers.base_chunker import BaseChunker
|
||||
from embedchain.config.add_config import ChunkerConfig
|
||||
from embedchain.helpers.json_serializable import register_deserializable
|
||||
|
||||
|
||||
@register_deserializable
|
||||
class JSONChunker(BaseChunker):
|
||||
"""Chunker for json."""
|
||||
|
||||
def __init__(self, config: Optional[ChunkerConfig] = None):
|
||||
if config is None:
|
||||
config = ChunkerConfig(chunk_size=1000, chunk_overlap=0, length_function=len)
|
||||
text_splitter = RecursiveCharacterTextSplitter(
|
||||
chunk_size=config.chunk_size,
|
||||
chunk_overlap=config.chunk_overlap,
|
||||
length_function=config.length_function,
|
||||
)
|
||||
super().__init__(text_splitter)
|
||||